
Tech
So you’ve heard these AI terms and nodded along; let’s fix that


Artificial intelligence is changing the world, and simultaneously inventing a whole new language to describe how it’s doing it. Spend five minutes reading about AI and you’ll run into LLMs, RAG, RLHF, and a dozen other terms that can make even very smart people in the tech world feel insecure. This glossary is our attempt to fix that. We update it regularly as the field evolves, so consider it a living document, much like the AI systems it describes.
Artificial general intelligence, or AGI, is a nebulous term. But it generally refers to AI that’s more capable than the average human at many, if not most, tasks. OpenAI CEO Sam Altman once described AGI as the “equivalent of a median human that you could hire as a co-worker.” Meanwhile, OpenAI’s charter defines AGI as “highly autonomous systems that outperform humans at most economically valuable work.” Google DeepMind’s understanding differs slightly from these two definitions; the lab views AGI as “AI that’s at least as capable as humans at most cognitive tasks.” Confused? Not to worry — so are experts at the forefront of AI research.
An AI agent refers to a tool that uses AI technologies to perform a series of tasks on your behalf — beyond what a more basic AI chatbot could do — such as filing expenses, booking tickets or a table at a restaurant, or even writing and maintaining code. However, as we’ve explained before, there are lots of moving pieces in this emergent space, so “AI agent” might mean different things to different people. Infrastructure is also still being built out to deliver on its envisaged capabilities. But the basic concept implies an autonomous system that may draw on multiple AI systems to carry out multistep tasks.
Think of API endpoints as “buttons” on the back of a piece of software that other programs can press to make it do things. Developers use these interfaces to build integrations — for example, allowing one application to pull data from another, or enabling an AI agent to control third-party services directly without a human manually operating each interface. Most smart home devices and connected platforms have these hidden buttons available, even if ordinary users never see or interact with them. As AI agents grow more capable, they are increasingly able to find and use these endpoints on their own, opening up powerful — and sometimes unexpected — possibilities for automation.
Given a simple question, a human brain can answer without even thinking too much about it — things like “which animal is taller, a giraffe or a cat?” But in many cases, you often need a pen and paper to come up with the right answer because there are intermediary steps. For instance, if a farmer has chickens and cows, and together they have 40 heads and 120 legs, you might need to write down a simple equation to come up with the answer (20 chickens and 20 cows).
In an AI context, chain-of-thought reasoning for large language models means breaking down a problem into smaller, intermediate steps to improve the quality of the end result. It usually takes longer to get an answer, but the answer is more likely to be correct, especially in a logic or coding context. Reasoning models are developed from traditional large language models and optimized for chain-of-thought thinking thanks to reinforcement learning.
(See: Large language model)
This is a more specific concept that an “AI agent,” which means a program that can take actions on its own, step by step, to complete a goal. A coding agent is a specialized version applied to software development. Rather than simply suggesting code for a human to review and paste in, a coding agent can write, test, and debug code autonomously, handling the kind of iterative, trial-and-error work that typically consumes a developer’s day. These agents can operate across entire codebases, spotting bugs, running tests, and pushing fixes with minimal human oversight. Think of it like hiring a very fast intern who never sleeps and never loses focus — though, as with any intern, a human still needs to review the work.
Although somewhat of a multivalent term, compute generally refers to the vital computational power that allows AI models to operate. This type of processing fuels the AI industry, giving it the ability to train and deploy its powerful models. The term is often a shorthand for the kinds of hardware that provides the computational power — things like GPUs, CPUs, TPUs, and other forms of infrastructure that form the bedrock of the modern AI industry.
A subset of self-improving machine learning in which AI algorithms are designed with a multi-layered, artificial neural network (ANN) structure. This allows them to make more complex correlations compared to simpler machine learning-based systems, such as linear models or decision trees. The structure of deep learning algorithms draws inspiration from the interconnected pathways of neurons in the human brain.
Deep learning AI models are able to identify important characteristics in data themselves, rather than requiring human engineers to define these features. The structure also supports algorithms that can learn from errors and, through a process of repetition and adjustment, improve their own outputs. However, deep learning systems require a lot of data points to yield good results (millions or more). They also typically take longer to train compared to simpler machine learning algorithms — so development costs tend to be higher.
(See: Neural network)
Diffusion is the tech at the heart of many art-, music-, and text-generating AI models. Inspired by physics, diffusion systems slowly “destroy” the structure of data — for example, photos, songs, and so on — by adding noise until there’s nothing left. In physics, diffusion is spontaneous and irreversible — sugar diffused in coffee can’t be restored to cube form. But diffusion systems in AI aim to learn a sort of “reverse diffusion” process to restore the destroyed data, gaining the ability to recover the data from noise.
Distillation is a technique used to extract knowledge from a large AI model with a ‘teacher-student’ model. Developers send requests to a teacher model and record the outputs. Answers are sometimes compared with a dataset to see how accurate they are. These outputs are then used to train the student model, which is trained to approximate the teacher’s behavior.
Distillation can be used to create a smaller, more efficient model based on a larger model with a minimal distillation loss. This is likely how OpenAI developed GPT-4 Turbo, a faster version of GPT-4.
While all AI companies use distillation internally, it may have also been used by some AI companies to catch up with frontier models. Distillation from a competitor usually violates the terms of service of AI API and chat assistants.
This refers to the further training of an AI model to optimize performance for a more specific task or area than was previously a focal point of its training — typically by feeding in new, specialized (i.e., task-oriented) data.
Many AI startups are taking large language models as a starting point to build a commercial product but are vying to amp up utility for a target sector or task by supplementing earlier training cycles with fine-tuning based on their own domain-specific knowledge and expertise.
(See: Large language model [LLM])
A GAN, or Generative Adversarial Network, is a type of machine learning framework that underpins some important developments in generative AI when it comes to producing realistic data — including (but not only) deepfake tools. GANs involve the use of a pair of neural networks, one of which draws on its training data to generate an output that is passed to the other model to evaluate.
The two models are essentially programmed to try to outdo each other. The generator is trying to get its output past the discriminator, while the discriminator is working to spot artificially generated data. This structured contest can optimize AI outputs to be more realistic without the need for additional human intervention. Though GANs work best for narrower applications (such as producing realistic photos or videos), rather than general purpose AI.
Hallucination is the AI industry’s preferred term for AI models making stuff up – literally generating information that is incorrect. Obviously, it’s a huge problem for AI quality.
Hallucinations produce GenAI outputs that can be misleading and could even lead to real-life risks — with potentially dangerous consequences (think of a health query that returns harmful medical advice).
The problem of AIs fabricating information is thought to arise as a consequence of gaps in training data. Hallucinations are contributing to a push toward increasingly specialized and/or vertical AI models — i.e. domain-specific AIs that require narrower expertise – as a way to reduce the likelihood of knowledge gaps and shrink disinformation risks.
Inference is the process of running an AI model. It’s setting a model loose to make predictions or draw conclusions from previously seen data. To be clear, inference can’t happen without training; a model must learn patterns in a set of data before it can effectively extrapolate from this training data.
Many types of hardware can perform inference, ranging from smartphone processors to beefy GPUs to custom-designed AI accelerators. But not all of them can run models equally well. Very large models would take ages to make predictions on, say, a laptop versus a cloud server with high-end AI chips.
[See: Training]
Large language models, or LLMs, are the AI models used by popular AI assistants, such as ChatGPT, Claude, Google’s Gemini, Meta’s AI Llama, Microsoft Copilot, or Mistral’s Le Chat. When you chat with an AI assistant, you interact with a large language model that processes your request directly or with the help of different available tools, such as web browsing or code interpreters.
LLMs are deep neural networks made of billions of numerical parameters (or weights, see below) that learn the relationships between words and phrases and create a representation of language, a sort of multidimensional map of words.
These models are created from encoding the patterns they find in billions of books, articles, and transcripts. When you prompt an LLM, the model generates the most likely pattern that fits the prompt.
(See: Neural network)
Memory cache refers to an important process that boosts inference (which is the process by which AI works to generate a response to a user’s query). In essence, caching is an optimization technique, designed to make inference more efficient. AI is obviously driven by high-octane mathematical calculations and every time those calculations are made, they use up more power. Caching is designed to cut down on the number of calculations a model might have to run by saving particular calculations for future user queries and operations. There are different kinds of memory caching, although one of the more well-known is KV (or key value) caching. KV caching works in transformer-based models, and increases efficiency, driving faster results by reducing the amount of time (and algorithmic labor) it takes to generate answers to user questions.
(See: Inference)
A neural network refers to the multi-layered algorithmic structure that underpins deep learning — and, more broadly, the whole boom in generative AI tools following the emergence of large language models.
Although the idea of taking inspiration from the densely interconnected pathways of the human brain as a design structure for data processing algorithms dates all the way back to the 1940s, it was the much more recent rise of graphical processing hardware (GPUs) — via the video game industry — that really unlocked the power of this theory. These chips proved well suited to training algorithms with many more layers than was possible in earlier epochs — enabling neural network-based AI systems to achieve far better performance across many domains, including voice recognition, autonomous navigation, and drug discovery.
(See: Large language model [LLM])
Open source refers to software — or, increasingly, AI models — where the underlying code is made publicly available for anyone to use, inspect, or modify. In the AI world, Meta’s Llama family of models is a prominent example; Linux is the famous historical parallel in operating systems. Open source approaches allow researchers, developers, and companies around the world to build on top of one another’s work, accelerating progress and enabling independent safety audits that closed systems cannot easily provide. Closed source means the code is private — you can use the product but not see how it works, as is the case with OpenAI’s GPT models — a distinction that has become one of the defining debates in the AI industry.
Parallelization means doing many things at the same time instead of one after another — like having 10 employees working on different parts of a project at the same time instead of one employee doing everything sequentially. In AI, parallelization is fundamental to both training and inference: modern GPUs are specifically designed to perform thousands of calculations in parallel, which is a big reason why they became the hardware backbone of the industry. As AI systems grow more complex and models grow larger, the ability to parallelize work across many chips and many machines has become one of the most important factors in determining how quickly and cost-effectively models can be built and deployed. Research into better parallelization strategies is now a field of study in its own right.
RAMageddon is the fun new term for a not-so-fun trend that is sweeping the tech industry: an ever-increasing shortage of random access memory, or RAM chips, which power pretty much all the tech products we use in our daily lives. As the AI industry has blossomed, the biggest tech companies and AI labs — all vying to have the most powerful and efficient AI — are buying so much RAM to power their data centers that there’s not much left for the rest of us. And that supply bottleneck means that what’s left is getting more and more expensive.
That includes industries like gaming (where major companies have had to raise prices on consoles because it’s harder to find memory chips for their devices), consumer electronics (where memory shortage could cause the biggest dip in smartphone shipments in more than a decade), and general enterprise computing (because those companies can’t get enough RAM for their own data centers). The surge in prices is only expected to stop after the dreaded shortage ends but, unfortunately, there’s not really much of a sign that’s going to happen anytime soon.
Like AGI, recursive self-improvement is a threshhold for how smart AI can get, and how little it may rely on humans. In the RSI scenario, AI models start improving themselves without human intervention, leading to a huge acceleration in capabilities and autonomy. In some tellings, this would be a cataclysmic moment akin to the singularity, a moment when AI models become immune to outside intervention. But RSI also describes a basic capability — can an AI model design its own successor? — which makes it much easier for engineers to try to build it. A number of recent AI startups have set out to build recursively self-improving models, but most of them dismiss the apocalyptic implications, presenting RSI as simply the next frontier for research.
Reinforcement learning is a way of training AI where a system learns by trying things and receiving rewards for correct answers — like training your beloved pet with treats, except the “pet” in this scenario is a neural network and the “treat” is a mathematical signal indicating success. Unlike supervised learning, where a model is trained on a fixed dataset of labeled examples, reinforcement learning lets a model explore its environment, take actions, and continuously update its behavior based on the feedback it receives. This approach has proven especially powerful for training AI to play games, control robots, and, more recently, sharpen the reasoning ability of large language models. Techniques like reinforcement learning from human feedback, or RLHF, are now central to how leading AI labs fine-tune their models to be more helpful, accurate, and safe.
When it comes to human-machine communication, there are some obvious challenges — people communicate using human language, while AI programs execute tasks through complex algorithmic processes informed by data. Tokens bridge that gap: they are the basic building blocks of human-AI communication, representing discrete segments of data that have been processed or produced by an LLM. They are created through a process called tokenization, which breaks down raw text into bite-sized units a language model can digest, similar to how a compiler translates human language into binary code a computer can understand. In enterprise settings, tokens also determine cost — most AI companies charge for LLM usage on a per-token basis, meaning the more a business uses, the more it pays.
So again, tokens are the small chunks of text — often parts of words rather than whole ones — that AI language models break language into before processing it; they are roughly analogous to “words” for the purposes of understanding AI workloads. Throughput refers to how much can be processed in a given period of time, so token throughput is essentially a measure of how much AI work a system can handle at once. High token throughput is a key goal for AI infrastructure teams, since it determines how many users a model can serve simultaneously and how quickly each of them receives a response. AI researcher Andrej Karpathy has described feeling anxious when his AI subscriptions sit idle — echoing the feeling he had as a grad student when expensive computer hardware wasn’t being fully utilized — a sentiment that captures why maximizing token throughput has become something of an obsession in the field.
Developing machine learning AIs involves a process known as training. In simple terms, this refers to data being fed in in order that the model can learn from patterns and generate useful outputs. Essentially, it’s the process of the system responding to characteristics in the data that enables it to adapt outputs towards a sought-for goal — whether that’s identifying images of cats or producing a haiku on demand.
Training can be expensive because it requires lots of inputs, and the volumes required have been trending upwards — which is why hybrid approaches, such as fine-tuning a rules-based AI with targeted data, can help manage costs without starting entirely from scratch.
[See: Inference]
A technique where a previously trained AI model is used as the starting point for developing a new model for a different but typically related task – allowing knowledge gained in previous training cycles to be reapplied.
Transfer learning can drive efficiency savings by shortcutting model development. It can also be useful when data for the task that the model is being developed for is somewhat limited. But it’s important to note that the approach has limitations. Models that rely on transfer learning to gain generalized capabilities will likely require training on additional data in order to perform well in their domain of focus
(See: Fine tuning)
Validation loss is a number that tells you how well an AI model is learning during training — and lower is better. Researchers track it closely as a kind of real-time report card, using it to decide when to stop training, when to adjust hyperparameters, or whether to investigate a potential problem. One of the key concerns it helps flag is overfitting, a condition in which a model memorizes its training data rather than truly learning patterns it can generalize to new situations. Think of it as the difference between a student who genuinely understands the material and one who simply memorized last year’s exam — validation loss helps reveal which one your model is becoming.
Weights are core to AI training, as they determine how much importance (or weight) is given to different features (or input variables) in the data used for training the system — thereby shaping the AI model’s output.
Put another way, weights are numerical parameters that define what’s most salient in a dataset for the given training task. They achieve their function by applying multiplication to inputs. Model training typically begins with weights that are randomly assigned, but as the process unfolds, the weights adjust as the model seeks to arrive at an output that more closely matches the target.
For example, an AI model for predicting housing prices that’s trained on historical real estate data for a target location could include weights for features such as the number of bedrooms and bathrooms, whether a property is detached or semi-detached, whether it has parking, a garage, and so on.
Ultimately, the weights the model attaches to each of these inputs reflect how much they influence the value of a property, based on the given dataset.
This article is updated regularly with new information.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
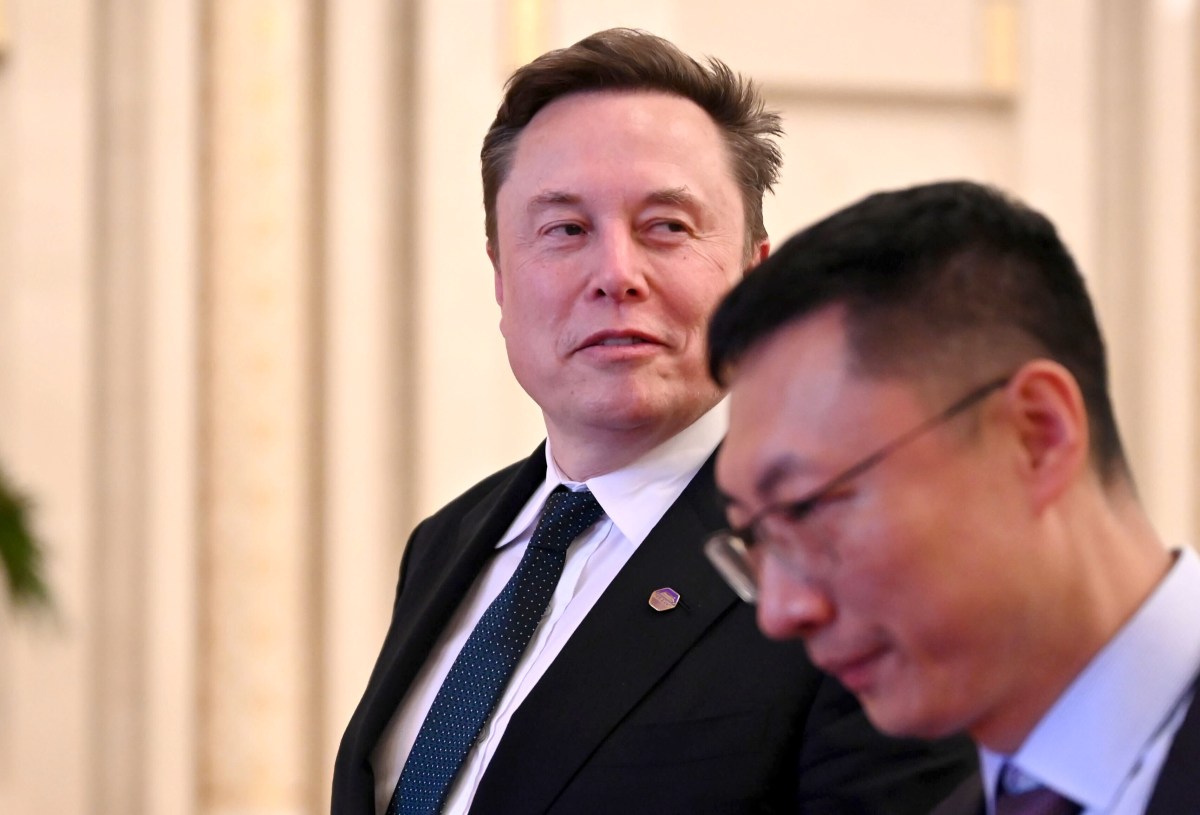
As SpaceX struggles to launch Starlink in India, Elon Musk has stepped up his attack on billionaire Mukesh Ambani, mockingly calling him the country’s “prime minister” to suggest he wields outsized control over its government and accusing him of blocking the satellite internet service from competing.
On Friday, Musk continued his criticism of the famed Reliance Industries’ chairperson in a post on X, arguing that Starlink could bring internet access to areas that remain unconnected, giving children more opportunities to learn, and helping small businesses reach customers worldwide.
“Naturally, you would prefer to maintain your monopolistic exploitation of the great people of India, but would you nonetheless consider allowing Starlink to compete?” Musk wrote.
Reliance Jio, Reliance Industries’ telecom arm, did not immediately respond to a request for comment.
Musk’s latest comments follow his accusations earlier this week that unnamed “oligarchs” were blocking Starlink’s launch in India to protect their business interests. India’s Ministry of Communications rejected the allegations, saying the country’s regulatory framework for satellite communications is “fair and non-discriminatory.” Musk then went further on Thursday, questioning Ambani’s influence in a separate post on X. “Is Ambani the real boss of India?” he asked.
SpaceX has spent years trying to launch Starlink in India. Last year, it even struck distribution agreements with Ambani’s Reliance Jio and Bharti Airtel, India’s second-largest telecom operator, to offer the service once it received the necessary approvals. However, Starlink has not yet received the go-ahead from New Delhi to begin commercial operations, despite securing key regulatory clearances.
In its Thursday statement, the Indian communication ministry said Starlink and two other licensed satellite operators are undergoing security assessments that must be completed before they can receive satellite spectrum. The ministry said all three are at “broadly the same regulatory stage,” rejecting Musk’s suggestion that Starlink was being singled out.
Jio and Airtel are also seeking to launch their satellite internet services in India. Jio has a joint venture with Luxembourg-based SES, while Airtel is a major shareholder in Eutelsat OneWeb, which is striving to offer satellite connectivity in the country.
India, the world’s most populous country with over a billion internet users, is a major market for Musk. But expanding there also means dealing with powerful business figures such as Ambani, whose Reliance conglomerate owns India’s largest telecom operator and works with Prime Minister Narendra Modi’s government on major projects.
Alongside Starlink’s delayed launch, Musk has also faced challenges expanding Tesla in India. The electric carmaker launched in the country last year after years of anticipation but registered just 699 vehicles in its first 12 months of deliveries, according to data cited by Electrek. Steep import duties pushed the Model Y’s launch price in India to nearly twice its U.S. price. Tesla lowered its prices earlier this year, but its cars remain considerably more expensive in India than in the U.S.
Before Musk’s latest attack, Starlink and Ambani’s Reliance Jio clashed over how to allocate satellite spectrum in India. Musk’s company wanted the spectrum to be assigned through an administrative process, while Jio pushed for an auction. Ultimately, New Delhi went ahead with Starlink and decided to allocate the spectrum administratively.
Starlink’s launch in India remains in limbo. India’s telecom minister Jyotiraditya Scindia on Friday pushed back against Musk’s allegations, saying the country “does not allow a monopoly in any sector.”
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
Tech
Anthropic can’t reliably control its AI agents. It’s cutting off its internal evals from the live internet instead
Anthropic said its models exploited websites on the internet, including some run by U.S. government agencies, and it will turn off live internet access for all of its internal evaluations until the frontier lab is sure it can monitor and control its AI agents.
The incidents, disclosed in a blog post, involved AI agents tasked to solve problems seeking resources on the internet. In the process, they exploited software flaws, avoided paywalls and anti-bot restrictions, used URL shortening services to smuggle information pass restrictions, and even submitted a false murder tip to the Philadelphia police.
Anthropic said it discovered these new issues in a review of its model’s activities that began in July, underscoring the lab’s lack of awareness of its software’s behavior.
Notably, the company said that alignment training was not yet sufficient for skills like search and computer use that are central to its pitch that AI agents will be used by any professional who relies on digital tools.
The behaviors Anthropic disclosed are similar to incidents involving OpenAI agents that collaborated to break into various websites in search of information, including some run by the Australian government.
Anthropic previously disclosed that its models had broken into external systems. The frontier lab said it considered today’s disclosures “significantly less severe from an alignment and security perspective” than those it announced before.
However, the lab still said it had “turned off live internet access” for “all our internal evaluations” until it is certain it can monitor and control its agents.
It’s not clear what that means, but Sydney Von Arx, the founder of Nightingale AI safety, told TechCrunch in an interview before this disclosure that developing models on a data center cut off from the open internet would be very challenging for researchers to access, and for the progress of the models, which benefit from internet access.
“You have to align them at some point,” Von Arx said. “If the AIs are released to production and never have access to the internet, that’s not a very useful tool.”
Anthropic said the behavior was a result of flaws in the lab’s training environments, which led the models to believe they would be rewarded for finding loopholes or avoiding restrictions, a behavior called “reward hacking.”
The company said it would stop running some of its evaluations or move them offline, and has built tooling to detect and block this behavior. This tooling was tested against the kind of incidents disclosed today and blocked them; it’s not clear what evidence will prompt Anthropic to return live internet access to its internal evaluations.
Anthropic also said it would migrate its internal AI agents to “centrally managed infrastructure with strong containment,” and is beginning to using safety classifiers more frequently to monitor those agents.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>

For a writer, the mechanical keyboard is a beautiful thing. They’re certainly not necessary for everyone, but a well designed mechanical keyboard can turn a tedious day of typing into an aesthetically pleasing experience.
Given that most of my days involve sitting at a desk for hours, having a keyboard that I enjoy using is a necessity. I first got a mechanical keyboard about two years ago — the Keychron K2 — and I’ve never looked back.
Keychron is one of the most prominent brands within the mechanical keyboard industry, having made a name for itself after initially launching via Kickstarter back in 2017. The company has since produced dozens of different keyboards (as well as keypads), and a variety of mouse models.
Unlike other electronics, there isn’t a whole lot to owning a mechanical keyboard. The simplicity is part of the appeal. You unbox them, set them up (the K2 comes with little tilt legs that give you a slightly better angle from which to type), and plug them in.
From here, you have a couple of different options. The K2 comes with a simple USB cable, but there’s also an option for Bluetooth connection. If you value a clean, minimalist workspace, Bluetooth is probably the way to go.
While I am loyal to my older Keychron K2, there are a few upgraded and newer versions to consider. Keychron has released a variety of new models over the past two years, with a broad range of features and price tags.
In many cases, the form factor is the draw. One of the more interesting releases, called the Keychron K8 HE Wireless Magnetic Switch Custom Keyboard, comes with an all-wood body and is equipped with an LED backlight. That one is substantially more expensive at around $200. The K2, meanwhile, costs $60. But if you’re into the look, maybe it’s worth it.
If you’re a gamer, there’s also Keychron’s C0 HE One-Handed 8K Keyboard, which is a keypad built for convenience and speed and has an industrial aesthetic to it. However, interested gamers will have to wait — as it’s currently sold out.
The company has also updated its K, Q, and V series keyboards, with many of those ranging in price from $100 to $200 depending on the features and model.
One of the appealing elements of owning a mechanical keyboards is the versatility. You can swap out the key caps for a wide variety of others (indeed, there’s a whole sub-market devoted to this) or make your own custom caps (I’ve never gone that overboard).
There is also the sound, of course. Some people balk at the accentuated noise of loudly clacking keys, but I’m a fan. In fact, the sound is one of the key selling points for a lot of consumers. The distinct auditory experience produced by said keyboards has even made its way into ASMR videos.
For me, the Keychron’s biggest selling point is its retro form factor. I get really nostalgic for old school electronics, and Keychron scratches this itch pretty well. It’s a beautiful looking device, that brings to mind a different era of computing, when the style was more workman-like, less minimalist.
As far as home office purchases go, you could do a lot worse than to pick yourself up a piece of hardware that makes your desk look like it just time-traveled from the 1990s.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
Singapore was a test run for F1’s first Monaco sprint. The drivers say it failed
Christian Benford returns, but Bills' secondary has tough task against Rams' receivers

Marie-Clémentine Dusabejambo On Directing Rwanda’s Oscar Submission ‘Ben’Imana’
-

 movies5 months ago
Search For Canadian TV Actor Stewart McLean Now Homicide Investigation
-

 Fashion9 years ago
These ’90s fashion trends are making a comeback in 2017
-
Fashion9 years ago
According to Dior Couture, this taboo fashion accessory is back
-
Fashion9 years ago
Model Jocelyn Chew’s Instagram is the best vacation you’ve ever had
-
Fashion9 years ago
Emily Ratajkowski channels back-to-school style
-
Fashion9 years ago
9 Celebrities who have spoken out about being photoshopped
-
 Anime4 months ago
Rurouni Kenshin: Hokkaido Arc Manga Takes 1-Issue Break – News
-

 Anime3 months ago
HIDIVE to Stream English Dubs for The World Is Dancing, The Forsaken Saintess and Her Foodie Roadtrip in Another World, The Dangers in My Heart: The Movie Anime – News