
Tech
So you’ve heard these AI terms and nodded along; let’s fix that


Artificial intelligence is changing the world, and simultaneously inventing a whole new language to describe how it’s doing it. Spend five minutes reading about AI and you’ll run into LLMs, RAG, RLHF, and a dozen other terms that can make even very smart people in the tech world feel insecure. This glossary is our attempt to fix that. We update it regularly as the field evolves, so consider it a living document, much like the AI systems it describes.
Artificial general intelligence, or AGI, is a nebulous term. But it generally refers to AI that’s more capable than the average human at many, if not most, tasks. OpenAI CEO Sam Altman once described AGI as the “equivalent of a median human that you could hire as a co-worker.” Meanwhile, OpenAI’s charter defines AGI as “highly autonomous systems that outperform humans at most economically valuable work.” Google DeepMind’s understanding differs slightly from these two definitions; the lab views AGI as “AI that’s at least as capable as humans at most cognitive tasks.” Confused? Not to worry — so are experts at the forefront of AI research.
An AI agent refers to a tool that uses AI technologies to perform a series of tasks on your behalf — beyond what a more basic AI chatbot could do — such as filing expenses, booking tickets or a table at a restaurant, or even writing and maintaining code. However, as we’ve explained before, there are lots of moving pieces in this emergent space, so “AI agent” might mean different things to different people. Infrastructure is also still being built out to deliver on its envisaged capabilities. But the basic concept implies an autonomous system that may draw on multiple AI systems to carry out multistep tasks.
Think of API endpoints as “buttons” on the back of a piece of software that other programs can press to make it do things. Developers use these interfaces to build integrations — for example, allowing one application to pull data from another, or enabling an AI agent to control third-party services directly without a human manually operating each interface. Most smart home devices and connected platforms have these hidden buttons available, even if ordinary users never see or interact with them. As AI agents grow more capable, they are increasingly able to find and use these endpoints on their own, opening up powerful — and sometimes unexpected — possibilities for automation.
Given a simple question, a human brain can answer without even thinking too much about it — things like “which animal is taller, a giraffe or a cat?” But in many cases, you often need a pen and paper to come up with the right answer because there are intermediary steps. For instance, if a farmer has chickens and cows, and together they have 40 heads and 120 legs, you might need to write down a simple equation to come up with the answer (20 chickens and 20 cows).
In an AI context, chain-of-thought reasoning for large language models means breaking down a problem into smaller, intermediate steps to improve the quality of the end result. It usually takes longer to get an answer, but the answer is more likely to be correct, especially in a logic or coding context. Reasoning models are developed from traditional large language models and optimized for chain-of-thought thinking thanks to reinforcement learning.
(See: Large language model)
This is a more specific concept that an “AI agent,” which means a program that can take actions on its own, step by step, to complete a goal. A coding agent is a specialized version applied to software development. Rather than simply suggesting code for a human to review and paste in, a coding agent can write, test, and debug code autonomously, handling the kind of iterative, trial-and-error work that typically consumes a developer’s day. These agents can operate across entire codebases, spotting bugs, running tests, and pushing fixes with minimal human oversight. Think of it like hiring a very fast intern who never sleeps and never loses focus — though, as with any intern, a human still needs to review the work.
Although somewhat of a multivalent term, compute generally refers to the vital computational power that allows AI models to operate. This type of processing fuels the AI industry, giving it the ability to train and deploy its powerful models. The term is often a shorthand for the kinds of hardware that provides the computational power — things like GPUs, CPUs, TPUs, and other forms of infrastructure that form the bedrock of the modern AI industry.
A subset of self-improving machine learning in which AI algorithms are designed with a multi-layered, artificial neural network (ANN) structure. This allows them to make more complex correlations compared to simpler machine learning-based systems, such as linear models or decision trees. The structure of deep learning algorithms draws inspiration from the interconnected pathways of neurons in the human brain.
Deep learning AI models are able to identify important characteristics in data themselves, rather than requiring human engineers to define these features. The structure also supports algorithms that can learn from errors and, through a process of repetition and adjustment, improve their own outputs. However, deep learning systems require a lot of data points to yield good results (millions or more). They also typically take longer to train compared to simpler machine learning algorithms — so development costs tend to be higher.
(See: Neural network)
Diffusion is the tech at the heart of many art-, music-, and text-generating AI models. Inspired by physics, diffusion systems slowly “destroy” the structure of data — for example, photos, songs, and so on — by adding noise until there’s nothing left. In physics, diffusion is spontaneous and irreversible — sugar diffused in coffee can’t be restored to cube form. But diffusion systems in AI aim to learn a sort of “reverse diffusion” process to restore the destroyed data, gaining the ability to recover the data from noise.
Distillation is a technique used to extract knowledge from a large AI model with a ‘teacher-student’ model. Developers send requests to a teacher model and record the outputs. Answers are sometimes compared with a dataset to see how accurate they are. These outputs are then used to train the student model, which is trained to approximate the teacher’s behavior.
Distillation can be used to create a smaller, more efficient model based on a larger model with a minimal distillation loss. This is likely how OpenAI developed GPT-4 Turbo, a faster version of GPT-4.
While all AI companies use distillation internally, it may have also been used by some AI companies to catch up with frontier models. Distillation from a competitor usually violates the terms of service of AI API and chat assistants.
This refers to the further training of an AI model to optimize performance for a more specific task or area than was previously a focal point of its training — typically by feeding in new, specialized (i.e., task-oriented) data.
Many AI startups are taking large language models as a starting point to build a commercial product but are vying to amp up utility for a target sector or task by supplementing earlier training cycles with fine-tuning based on their own domain-specific knowledge and expertise.
(See: Large language model [LLM])
A GAN, or Generative Adversarial Network, is a type of machine learning framework that underpins some important developments in generative AI when it comes to producing realistic data — including (but not only) deepfake tools. GANs involve the use of a pair of neural networks, one of which draws on its training data to generate an output that is passed to the other model to evaluate.
The two models are essentially programmed to try to outdo each other. The generator is trying to get its output past the discriminator, while the discriminator is working to spot artificially generated data. This structured contest can optimize AI outputs to be more realistic without the need for additional human intervention. Though GANs work best for narrower applications (such as producing realistic photos or videos), rather than general purpose AI.
Hallucination is the AI industry’s preferred term for AI models making stuff up – literally generating information that is incorrect. Obviously, it’s a huge problem for AI quality.
Hallucinations produce GenAI outputs that can be misleading and could even lead to real-life risks — with potentially dangerous consequences (think of a health query that returns harmful medical advice).
The problem of AIs fabricating information is thought to arise as a consequence of gaps in training data. Hallucinations are contributing to a push toward increasingly specialized and/or vertical AI models — i.e. domain-specific AIs that require narrower expertise – as a way to reduce the likelihood of knowledge gaps and shrink disinformation risks.
Inference is the process of running an AI model. It’s setting a model loose to make predictions or draw conclusions from previously seen data. To be clear, inference can’t happen without training; a model must learn patterns in a set of data before it can effectively extrapolate from this training data.
Many types of hardware can perform inference, ranging from smartphone processors to beefy GPUs to custom-designed AI accelerators. But not all of them can run models equally well. Very large models would take ages to make predictions on, say, a laptop versus a cloud server with high-end AI chips.
[See: Training]
Large language models, or LLMs, are the AI models used by popular AI assistants, such as ChatGPT, Claude, Google’s Gemini, Meta’s AI Llama, Microsoft Copilot, or Mistral’s Le Chat. When you chat with an AI assistant, you interact with a large language model that processes your request directly or with the help of different available tools, such as web browsing or code interpreters.
LLMs are deep neural networks made of billions of numerical parameters (or weights, see below) that learn the relationships between words and phrases and create a representation of language, a sort of multidimensional map of words.
These models are created from encoding the patterns they find in billions of books, articles, and transcripts. When you prompt an LLM, the model generates the most likely pattern that fits the prompt.
(See: Neural network)
Memory cache refers to an important process that boosts inference (which is the process by which AI works to generate a response to a user’s query). In essence, caching is an optimization technique, designed to make inference more efficient. AI is obviously driven by high-octane mathematical calculations and every time those calculations are made, they use up more power. Caching is designed to cut down on the number of calculations a model might have to run by saving particular calculations for future user queries and operations. There are different kinds of memory caching, although one of the more well-known is KV (or key value) caching. KV caching works in transformer-based models, and increases efficiency, driving faster results by reducing the amount of time (and algorithmic labor) it takes to generate answers to user questions.
(See: Inference)
A neural network refers to the multi-layered algorithmic structure that underpins deep learning — and, more broadly, the whole boom in generative AI tools following the emergence of large language models.
Although the idea of taking inspiration from the densely interconnected pathways of the human brain as a design structure for data processing algorithms dates all the way back to the 1940s, it was the much more recent rise of graphical processing hardware (GPUs) — via the video game industry — that really unlocked the power of this theory. These chips proved well suited to training algorithms with many more layers than was possible in earlier epochs — enabling neural network-based AI systems to achieve far better performance across many domains, including voice recognition, autonomous navigation, and drug discovery.
(See: Large language model [LLM])
Open source refers to software — or, increasingly, AI models — where the underlying code is made publicly available for anyone to use, inspect, or modify. In the AI world, Meta’s Llama family of models is a prominent example; Linux is the famous historical parallel in operating systems. Open source approaches allow researchers, developers, and companies around the world to build on top of one another’s work, accelerating progress and enabling independent safety audits that closed systems cannot easily provide. Closed source means the code is private — you can use the product but not see how it works, as is the case with OpenAI’s GPT models — a distinction that has become one of the defining debates in the AI industry.
Parallelization means doing many things at the same time instead of one after another — like having 10 employees working on different parts of a project at the same time instead of one employee doing everything sequentially. In AI, parallelization is fundamental to both training and inference: modern GPUs are specifically designed to perform thousands of calculations in parallel, which is a big reason why they became the hardware backbone of the industry. As AI systems grow more complex and models grow larger, the ability to parallelize work across many chips and many machines has become one of the most important factors in determining how quickly and cost-effectively models can be built and deployed. Research into better parallelization strategies is now a field of study in its own right.
RAMageddon is the fun new term for a not-so-fun trend that is sweeping the tech industry: an ever-increasing shortage of random access memory, or RAM chips, which power pretty much all the tech products we use in our daily lives. As the AI industry has blossomed, the biggest tech companies and AI labs — all vying to have the most powerful and efficient AI — are buying so much RAM to power their data centers that there’s not much left for the rest of us. And that supply bottleneck means that what’s left is getting more and more expensive.
That includes industries like gaming (where major companies have had to raise prices on consoles because it’s harder to find memory chips for their devices), consumer electronics (where memory shortage could cause the biggest dip in smartphone shipments in more than a decade), and general enterprise computing (because those companies can’t get enough RAM for their own data centers). The surge in prices is only expected to stop after the dreaded shortage ends but, unfortunately, there’s not really much of a sign that’s going to happen anytime soon.
Like AGI, recursive self-improvement is a threshhold for how smart AI can get, and how little it may rely on humans. In the RSI scenario, AI models start improving themselves without human intervention, leading to a huge acceleration in capabilities and autonomy. In some tellings, this would be a cataclysmic moment akin to the singularity, a moment when AI models become immune to outside intervention. But RSI also describes a basic capability — can an AI model design its own successor? — which makes it much easier for engineers to try to build it. A number of recent AI startups have set out to build recursively self-improving models, but most of them dismiss the apocalyptic implications, presenting RSI as simply the next frontier for research.
Reinforcement learning is a way of training AI where a system learns by trying things and receiving rewards for correct answers — like training your beloved pet with treats, except the “pet” in this scenario is a neural network and the “treat” is a mathematical signal indicating success. Unlike supervised learning, where a model is trained on a fixed dataset of labeled examples, reinforcement learning lets a model explore its environment, take actions, and continuously update its behavior based on the feedback it receives. This approach has proven especially powerful for training AI to play games, control robots, and, more recently, sharpen the reasoning ability of large language models. Techniques like reinforcement learning from human feedback, or RLHF, are now central to how leading AI labs fine-tune their models to be more helpful, accurate, and safe.
When it comes to human-machine communication, there are some obvious challenges — people communicate using human language, while AI programs execute tasks through complex algorithmic processes informed by data. Tokens bridge that gap: they are the basic building blocks of human-AI communication, representing discrete segments of data that have been processed or produced by an LLM. They are created through a process called tokenization, which breaks down raw text into bite-sized units a language model can digest, similar to how a compiler translates human language into binary code a computer can understand. In enterprise settings, tokens also determine cost — most AI companies charge for LLM usage on a per-token basis, meaning the more a business uses, the more it pays.
So again, tokens are the small chunks of text — often parts of words rather than whole ones — that AI language models break language into before processing it; they are roughly analogous to “words” for the purposes of understanding AI workloads. Throughput refers to how much can be processed in a given period of time, so token throughput is essentially a measure of how much AI work a system can handle at once. High token throughput is a key goal for AI infrastructure teams, since it determines how many users a model can serve simultaneously and how quickly each of them receives a response. AI researcher Andrej Karpathy has described feeling anxious when his AI subscriptions sit idle — echoing the feeling he had as a grad student when expensive computer hardware wasn’t being fully utilized — a sentiment that captures why maximizing token throughput has become something of an obsession in the field.
Developing machine learning AIs involves a process known as training. In simple terms, this refers to data being fed in in order that the model can learn from patterns and generate useful outputs. Essentially, it’s the process of the system responding to characteristics in the data that enables it to adapt outputs towards a sought-for goal — whether that’s identifying images of cats or producing a haiku on demand.
Training can be expensive because it requires lots of inputs, and the volumes required have been trending upwards — which is why hybrid approaches, such as fine-tuning a rules-based AI with targeted data, can help manage costs without starting entirely from scratch.
[See: Inference]
A technique where a previously trained AI model is used as the starting point for developing a new model for a different but typically related task – allowing knowledge gained in previous training cycles to be reapplied.
Transfer learning can drive efficiency savings by shortcutting model development. It can also be useful when data for the task that the model is being developed for is somewhat limited. But it’s important to note that the approach has limitations. Models that rely on transfer learning to gain generalized capabilities will likely require training on additional data in order to perform well in their domain of focus
(See: Fine tuning)
Validation loss is a number that tells you how well an AI model is learning during training — and lower is better. Researchers track it closely as a kind of real-time report card, using it to decide when to stop training, when to adjust hyperparameters, or whether to investigate a potential problem. One of the key concerns it helps flag is overfitting, a condition in which a model memorizes its training data rather than truly learning patterns it can generalize to new situations. Think of it as the difference between a student who genuinely understands the material and one who simply memorized last year’s exam — validation loss helps reveal which one your model is becoming.
Weights are core to AI training, as they determine how much importance (or weight) is given to different features (or input variables) in the data used for training the system — thereby shaping the AI model’s output.
Put another way, weights are numerical parameters that define what’s most salient in a dataset for the given training task. They achieve their function by applying multiplication to inputs. Model training typically begins with weights that are randomly assigned, but as the process unfolds, the weights adjust as the model seeks to arrive at an output that more closely matches the target.
For example, an AI model for predicting housing prices that’s trained on historical real estate data for a target location could include weights for features such as the number of bedrooms and bathrooms, whether a property is detached or semi-detached, whether it has parking, a garage, and so on.
Ultimately, the weights the model attaches to each of these inputs reflect how much they influence the value of a property, based on the given dataset.
This article is updated regularly with new information.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>

In less than 48 hours, the doors open for TechCrunch Disrupt 2026 at San Francisco’s Moscone West. Save up to $100 on your ticket before prices increase at the door. Don’t forget to get a second pass at 50% off. Register now.
On October 13-15, more than 10,000 founders, investors, and tech leaders will be showing up to make the connections that’ll change their trajectory. More than 250 speakers are getting ready to take the stage across 200+ sessions. Discover 300+ startups showcasing what’s next. Register now before rates hike at the door on October 13, 8 a.m. PT.

Hear the conversations shaping tech right now
If you’re coming for the conference program, 200+ sessions across six stages, roundtables, and breakouts will bring you closer to the people making decisions inside some of technology’s most talked-about companies.
Hear from leaders including RJ Scaringe of Rivian, Mark Wahlberg, Alexa von Tobel of Inspired Capital, Andrew Feldman of Cerebras Systems, Cat de Jong of Anthropic, Les Karpas of NVIDIA, and many more — with conversations spanning AI, robotics, infrastructure, investment, startup growth, fintech, climate, and the realities of building at scale.

Explore what will make waves in the tech ecosystem
If your priority is discovery rather than sessions, spend your time in the bustling Expo Hall, where you can see tomorrow’s breakthroughs, speak directly with the companies behind them, and find out where big ideas are already becoming real products and businesses. It’s here that you’ll also meet the top 200, hand-picked startups that made it into Startup Battlefield.
Disrupt gives you the flexibility to focus on the experience that matters to you — or mix both across three days.

Clock is ticking. Get your pass before Disrupt doors open.
The global startup ecosystem is gearing up for TechCrunch Disrupt 2026, and the countdown is almost over. Will you be there?
Don’t miss your chance to save before door prices take effect! Grab your pass now to save up to $100 and get a second pass of the same ticket type at 50% off. Bringing a group of four or more? Unlock additional group discounts.
Recently laid off? Don’t miss out on the opportunities at Disrupt. Take advantage of our Layoff to Liftoff Ticket Program and get an Expo+ Pass for just $75.

When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
TechCrunch Disrupt 2026 is built around one question for founders: How do you build an enduring company in the AI era? For investors, it’s the opposite: How do you find that company before someone else does?
At Disrupt, the volume and competition are the point for investors, not a drawback. Year after year, investors who’ve explored the Expo Halls, met founders, and learned from peers at panels and Side Events have proven why you need to be on the ground to get ahead of the curve.
Consider that every founder pitching during the Startup Battlefield competition does so in front of a packed room of VCs. Why? Because they know their next cohort could be sitting right there. All it takes is making the trip to San Francisco this October 13-15.
This guide is for the investors who recognize that three days spent at Moscone West are well worth it and who plan to walk away with the insights and prospects that yield returns.
And speaking of returns, we have up to $100 in savings with our current ticket tiers, which end Monday, October 12 at 11:59 p.m. PT, so act swiftly to get an even greater ROI on Disrupt. And if you’ve recently been laid off, we have a $75 Expo+ Pass offer to help you make more connections to find your next opportunity.
Let’s dive in!
How Disrupt works for different investors
Disrupt features numerous tracks, depending on the check sizes you’re able to write and the stage of startup you specialize in.
Angel, pre-seed, scout
If you’re coming to build out your portfolio of early bets and get in on rounds before they’re priced, prioritize the Startup Battlefield 200 semifinalist pitches, the Builders Stage, and the Expo Hall.
Seed, Series A
Disrupt will be all about volume and speed of qualified deal flow. Prioritize the founder list, our curated 1:1 meetings, and the Deal Flow Café.
Growth, late stage
This stage is best suited for those coming to the event as much for market intelligence and strategic partnership scouting as for deal sourcing. Prioritize the Smart Money and Smart Systems Stages, as well as the exclusive StrictlyVC investor-only session.
Why Disrupt?
More than 20,000 curated meetings take place over just three days, within dedicated environments like investor receptions and structured networking sessions. Investor-founder connections aren’t hallway luck –they’re built into Disrupt’s infrastructure.
You get direct access to 200 pitch-ready, TechCrunch-vetted startups through Startup Battlefield 200. And we’ll put an emphasis on “vetted.” Our Startup Battlefield team, working alongside TechCrunch’s incredibly discerning team of editors and writers, has done a significant amount of diligence for you already.
Past speakers have included investors like Elad Gil and Vinod Khosla, and this year’s lineup puts you in the room with the operators you’re underwriting, too. We’re talking Rivian’s RJ Scaringe, Amazon’s Panos Panay, Replit’s Amjad Masad, and Cerebras’ Andrew Feldman, just for starters.
The Disrupt crowd is your signal. With a mix of 10,000 founders, investors, and operators filling Moscone West, the companies worth knowing will get discovered by someone. This is your chance to make sure it’s you.
Startup Battlefield 200 is a sourcing engine, not just a pitch competition

For founders, Startup Battlefield is a visibility engine and a trial by fire. For investors, it’s a filtered shortlist that the TechCrunch team has spent months narrowing down for you.
Consider that:
- 200 pre-Series A startups, handpicked by our Startup Battlefield and editorial teams and sharpened through the SB 200 program, are competing for $100,000 in equity-free funding.
- Battlefield alumni have collectively raised over $32 billion and produced 250+ exits, which is evidence we produce fundable companies.
Startup Battlefield is intensely competitive. Thousands of global startups apply, while just 200 make the cut and only a handful reach the finals. That funnel is doing your top-of-pipeline filtering for you before you ever take a meeting. If you’re not circling around these startups, your competitors are.
The exclusive access that an Investor Pass grants
We have several different passes for Disrupt, and by joining the community via an Investor Pass, you get access to perks like…
The Deal Flow Café
This is a space exclusively for founders and investors, fostering impromptu run-ins with founders actively seeking capital. Grab coffee or a beverage of choice, explore opportunities, and start conversations that can turn into your next deal.
The founder list
You’ll get early access to the full list of Disrupt founders looking for connections with investors. The next addition to your portfolio can be identified before the event even begins, giving you more time to find even more opportunities.
Curated meetings
Through the Disrupt app, you can schedule 1:1 and small-group meetings with founders matching your focus areas, with AI helping match you by mutual interests instead of waiting on fate.
The investors who make the most out of Disrupt don’t leave sourcing to chance — they’ve already scanned the available resources and set up their agendas in advance.
The Disrupt programming that matters most to Investors

Our editorially curated programming, including all three days of sessions and panels, is available here, stretching across six stages, breakout sessions, roundtables, and Side Events. Here are some of the stages that might be of interest:
The Smart Money Stage: Interested in capital markets, embedded finance, and stablecoins? Everything within the fintech realm, especially within the intersection of AI, is included.
The Smart Systems Stage: It’s all about compute, infrastructure, and energy economics. If you need to build a justification for underwriting AI infrastructure bets, this is the place to start.
The AI Stage and Real World AI Stages: Get market intelligence on where the fastest-growing startups are deploying, not just building.
The Disrupt Stage: This is where operators and CEOs set the narrative your current and future portfolio companies will be measured against.
Is Disrupt 2026 worth it?
Disrupt’s value isn’t found in the size of the crowd, though that certainly helps. It’s in the potential, the expertise, the value of that crowd and the feedback it gives you. With so much overlapping investor attention, the companies worth knowing are getting found fast — regardless of whether you’re in the room. The cost of attending is a ticket and three days of your time. The cost of not attending is finding out about your next portfolio company from someone else’s term sheet.
Disrupt 2026 logistics for investors
We’ve gone in depth about the benefits to you, your portfolio, and the opportunities Disrupt offers you. But there are always matters of hotels, expenses, and travel to sort out. Our Disrupt site has the bulk of these issues covered, but to tackle some common questions and pressing opportunities:
Disrupt passes are discounted until October 13, after which we’ll have higher walk-up rates. That means up to $100 discounts on tickets relative to their final prices.
For your hotel needs, we have partnerships with several stellar hotels near Moscone West. You’ll get exclusive discounts, easy access to Disrupt and anything else you might want to explore in San Francisco, and yes, you’ll get points for your accommodations.
If you’re bringing a large cohort or are interested in having a company in your portfolio take part in our Expo Hall to get wider visibility, check out our bulk ticket options here and our Exhibit Table options here.
For all other questions, you can explore our full Disrupt page to find more specific FAQs, and we hope to see you in San Francisco this year!

When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
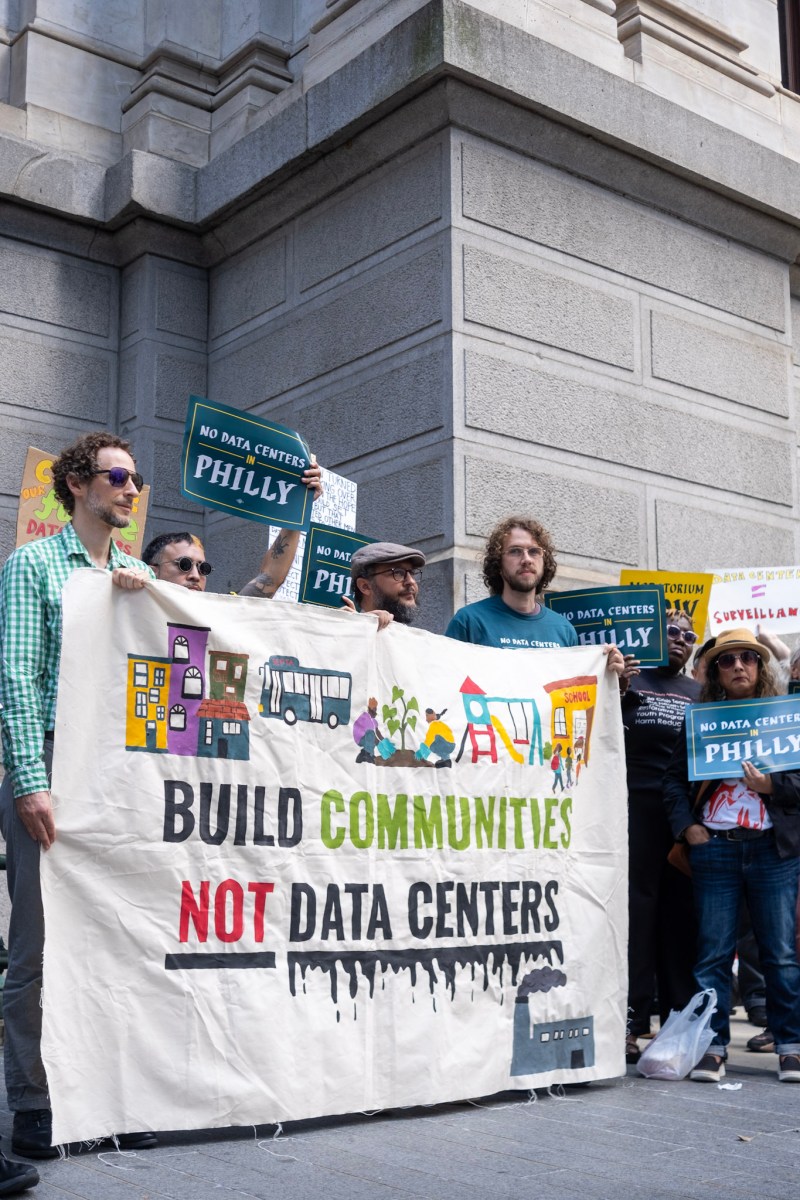
Amazon recently followed Microsoft’s lead and said it will no longer use nondisclosure agreements (NDAs) while negotiating with local governments over data centers.
On the latest episode of TechCrunch’s Equity podcast, Sean O’Kane, Rebeccan Bellan and I discussed Amazon’s announcement, which came in the middle of a longer blog post making the case that data centers are actually good for communities.
Rebecca was a bit skeptical that the recent spate of data center moratoriums will have a lasting effect, especially since the moratoriums only last for a year or two and “these data centers aren’t coming online for the next two, three, four, five years,” though I countered that data center backers definitely seem worried.
Sean, meanwhile, suggested that a big reason for the backlash is the industry’s poor communication.
“We’ve seen, through a lot of the controversy and backlash to AI and data centers, that the industry just does a really poor job explaining itself, and that they are obviously and constantly frustrated with the fact that most people can’t envision a world in which this stuff is useful for them,” he said.
Keep reading for a preview of our conversation, edited for length and clarity.
Sean O’Kane: It’s an interesting thing that it was sort of buried in the blog post and part of a larger story that Amazon’s clearly trying to tell. I guess I understand why they weren’t putting it in the foreground, but to me, this is at the root of so many of the problems that the tech industry currently faces when it comes to AI broadly, but data centers in particular.
There are so many things that could be said about whether or not people should be worried about the effect that data centers have on their property values, on their electricity bills, on their water usage in the area, and whether or not those things are real problems, inflated problems, etc. etc.
I think so much of that just really goes back to the fact that a lot of these projects are being negotiated essentially in secret. Sometimes they’re being negotiated [with the public knowing] that it’s a data center, but just not knowing who’s actually going to use it or occupy it at any point.
This is a long-standing issue with the tech industry. I always go back to the mid-2010s when Uber was expanding really fast. Uber was one of the companies that really used this tactic a ton when it came to working with local governments. In particular, I remember I was working at The Verge at the time and we had a freelancer write a story about a city outside of Orlando where Uber was trying to negotiate tax subsidies to subsidize rides for people to use public transit after the Uber trip.
The whole thing was negotiated in secret. And not only that, which was frustrating on its face, but also, because of the secrecy, you could just see Uber getting really comfortable with asking for a lot of other stuff, too.
So there needs to be more of this. I’m glad Amazon’s doing this. We’ll see if it actually does have any positive effect, but people are pretty entrenched right now.
Rebecca Bellan: Yeah, I’m curious about what effect this will have and whether it will lead to communities successfully delaying or or killing any infrastructure that the companies need to build. What I’ve heard from some people I’ve spoken to, who deal with data centers every day, a lot of these moratoriums that are getting passed — and there are a significant number of them, including one recently in San Francisco, which is pretty ironic — but they’re only for like a year or two years.
But these data centers aren’t coming online for the next two, three, four, five years. All of the buildouts are going to be massively delayed for a number of reasons from zoning to funding. Of course, if the pushback keeps going, then it might have an effect, but I often wonder just how much of an effect this political pushback is having on this.
Anthony Ha: The moratorium I’m most familiar with is the one in New York. I believe it’s a one year moratorium, and that’s on permits for large projects. [Technically, it’s until the state finalizes an environmental review process, which is expected to take a year.]
So already, there’s some wiggle room within that. And often, they’re framed as: “It’s not like we think [data centers are] bad, let’s not do this. It’s [that] we need to take the time to study this.” Which gives them a lot of room to say later on, “Actually, we’ve decided this is great. We love it.”
But you can tell that the people trying to build these data centers are worried, which is why you have these unhinged tweets from people like Trump or David Sacks. Only time will tell in terms how long and how deep that [community] resistance is, but I do think they are worried.
It’s also noteworthy that Microsoft, earlier this year, made a similar announcement about not using NDAs. I don’t think that getting rid of the NDAs automatically is going to make the people who opposed these data centers be like, “Great, let’s let’s do it. I’m in.” But I think the beginning of that conversation is, “Well, we don’t even know what the heck you’re doing, because you’ve negotiated all this stuff in secret.” So it does seem like a good first step.
Sean: The larger problem here is just a communication problem, right? This is a problem I think that goes across the entire tech industry, but it’s especially acute now, because we’re living in the era of “going direct” and “you don’t need to talk to the media, the media is dead,” etc.
And I’m not trying to beat that horse, because we’re in the media and [we] think we’re still relevant. But we’ve seen, through a lot of the controversy and backlash to AI and data centers, that the industry just does a really poor job explaining itself, and that they are obviously and constantly frustrated with the fact that most people can’t envision a world in which this stuff is useful for them. And that’s because, a lot of time, the [technological] ability’s not there, and in part because they’re just not explaining it well.
I wrote a story last week about how it’s been a year since we’ve really heard Tesla beating its own drum about building towards what it originally was calling “sustainable abundance” and is now “amazing abundance” as its mission statement. It’s just wild to me that we’re a year into that, and the company still doesn’t have a very good definition of it, especially considering that they released this whole multi-page PDF laying it out when they announced this, and even Tesla’s biggest fans criticized Elon Musk and Tesla for how unspecific it was. It read like LLM nonsense.
Anthony: One of the things this has made me think about is just the narrative and this sense that for a while, it really felt like it was being pushed down our throats — this idea of, “This is inevitable, this AI-driven future, and get on board or you’re just going to be left behind.”
Obviously that future is barreling ahead in a lot of ways, but in a few key ways, there have been these obstacles. What I’ve really liked about that is this sense of “No, you actually have to make the case for it.” You can’t just say, “This is the future, shut up.”
And then specifically about Tesla and the abundance thing, what was shocking to me is not so much that they haven’t come up with a definition of abundance, but that that was a promise that they were making in the first place. I think [that] speaks to how strange our relationship to Tesla, and particularly the people who are invested and ride-or-die for Elon, [has become.] It’s not about, is this company going to sell a lot of cars? It’s about this vision for remaking society. Or at least, that’s what they’re being sold.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
‘The Rookie’ Season 9 & Spinoff ‘North’ Get Premiere Dates, Teaser

Manchester City: A statement win but does it carry weight in a season of limbo?
Drake Maye's huge day has Patriots surging and leaves Raiders reeling
-

 movies5 months ago
Search For Canadian TV Actor Stewart McLean Now Homicide Investigation
-

 Fashion9 years ago
These ’90s fashion trends are making a comeback in 2017
-
Fashion9 years ago
According to Dior Couture, this taboo fashion accessory is back
-
Fashion9 years ago
Model Jocelyn Chew’s Instagram is the best vacation you’ve ever had
-
Fashion9 years ago
Emily Ratajkowski channels back-to-school style
-
Fashion9 years ago
9 Celebrities who have spoken out about being photoshopped
-
 Anime4 months ago
Rurouni Kenshin: Hokkaido Arc Manga Takes 1-Issue Break – News
-

 Anime3 months ago
HIDIVE to Stream English Dubs for The World Is Dancing, The Forsaken Saintess and Her Foodie Roadtrip in Another World, The Dangers in My Heart: The Movie Anime – News