
Tech
Social Media Bans for Kids Need Smarter Safety Design


Even before France approved legislation banning social media for children under 15 last January, 13-year-old Benjamin was already wondering what life without social media would look like. “If we want to play football, we won’t be able to organize it. What will we do? Send letters instead?” he joked in an interview for Le Monde.
His reaction captured the central challenge behind the growing wave of youth social media bans: Removing access is one thing; understanding what those platforms mean in children’s lives is another.
Within weeks of Australia’s similar ban, the country’s eSafety Commissioner reported that platforms had restricted access to 4.7 million under-16 accounts. Two months later, though, one in five Australian teenagers under 16 was still using TikTok and Snapchat, according to a parental-control data company. But even if all children’s social media accounts were to disappear, do such bans actually make children safer online?
Governments are moving ahead without answering that question as they follow Australia’s lead. Indonesia’s child safety framework, which took effect in March, bars children under 16 from holding accounts on “high-risk” platforms. The UK government has announced plans to ban social media for under-16s, add default overnight social media curfews for 16- and 17-year-olds, and extend child-safety rules to cover risky AI features. And on 17 September, the European Commission proposed the EU KIDS Act, which would bar children under 13 from social media, set 15 as the EU-wide minimum age for opening an account independently, and require platforms to show that their services are age-appropriate and safe by design.
But based on my experience working on Child Online Protection initiatives with the International Telecommunication Union (ITU) across Southeast Asia and the Pacific, I know the bans don’t address the real problems. Instead, we should be paying more attention to the systems that generate harm in the first place—namely, recommender algorithms, engagement-maximizing design, opaque moderation, and extractive data practices.
Account removals are not the same as online child safety
My experience working on protecting children’s online safety has taught me three main lessons:
First, the public institutions responsible for child online protection often lack the staff, budget, or technical capacity to enforce complex online safety policies.
Indonesia is illustrative. A 2026 UNICEF evaluation found capacity constraints among service providers, long-term funding uncertainty, and a need for specialized personnel. At the local level, some staff lacked digital skills, while budget constraints left some areas reliant on external support.
Second, many children, and often their parents, lack the digital literacy and critical thinking skills needed to navigate online risks safely. My policy research on child online protection in Indonesia, published earlier this year in Digital Society, found substantial gaps that account removals cannot repair: Many children lacked guidance on navigating the internet safely, and large numbers did not know how to report harmful experiences.
And third, the platforms have limited independent oversight as they identify underage users, design age-verification systems, and report their own compliance. In Indonesia, platforms themselves are responsible for carrying out age verification, while the Ministry of Communication and Digital Affairs oversees compliance. TikTok’s appeals process for users flagged as underage, for instance, can require a government-issued ID and selfies, which is a problem because it involves collecting the additional personal data on an ID card, beyond that needed to confirm age. Will government regulators ensure that TikTok handles that data responsibly?
The privacy paradox of proving age
Every age-based ban creates an engineering problem: How can a platform reliably determine that a user is old enough, without intruding on other information? Governments and companies may use identity documents, parental authorization, app-store checks, or facial age estimation. Each approach has trade-offs between accuracy, privacy, accessibility, and resistance to circumvention.
There are also technical issues. One tool, facial age estimation, draws on enormous databases but it is probabilistic, not exact, because people vary so much. It’s also been shown to misclassify both children and adults.
The challenge should not merely be to “verify age.” It should be to prove that someone is above a threshold, without disclosing their identity, birth date, or other information third parties might use to create a marketing profile. The European Commission’s age-verification blueprint challenges companies to verify ages without collecting all that additional information.
Privacy-preserving technologies offer promising ways to achieve this. Zero-Knowledge Proofs (ZKPs) can confirm that someone meets an age threshold without revealing their identity or exact date of birth. W3C Verifiable Credentials are cryptographically verifiable digital claims that can disclose only the information needed, such as “over 16.” And device-based age signals can allow a phone or app store to share an age range without revealing a user’s exact birth date. But these methods still require rigorous security testing, common standards, independent oversight, and clear limits on data retention. Otherwise, poorly designed child-safety policies risk creating permanent identity infrastructures in which businesses, not people, control personal data.
Where connection goes when a platform closes
Blocking access to a platform redirects some young people, but not always where expected. Early anecdotal reports in Australia pointed to teenagers migrating to smaller, less-regulated platforms like Yope, a pattern the Cato Institute flagged as a “whack-a-mole” problem for regulators. But industry data collected two months later found no broad-based shift of that kind, aside from a small uptick in WhatsApp use. Many teens simply found a way to stay on the banned platforms.
This points to a deeper gap in current society: the erosion of youth “third places“ physical spaces where young people have room to socialize and build identity outside home and school. As those spaces have diminished, commercial communications platforms have absorbed that role.
For many teenagers, social media workarounds are merely inconvenient. But for isolated, marginalized, disabled, or LGBTQ+ youth who depend on online communities for support that’s otherwise unavailable, displacement can mean losing certain kinds of belonging, or having to move to a platform with even weaker oversight.
How to design safer online systems for children
If blanket social media bans don’t work, then what will? The platforms have created many of the conditions that governments are now trying to contain: engagement-optimized recommenders, intrusive data practices, weak safeguards against unwanted contact, and features such as infinite scroll, autoplay, streaks, and persistent notifications.
These design patterns increasingly face regulatory scrutiny, including under the European Union’s Digital Services Act. A 2026 study from the 5Rights Foundation that tracked children’s device use minute by minute found that the user interfaces shape children’s attention, sleep, and well-being in real time.
A more durable response would regulate those interfaces directly, treating children as legitimate users whose privacy, agency, and well-being are required protections, not afterthoughts. That means designing for safety from the outset. One example would be for children’s apps to have high-privacy defaults, such as private accounts and location sharing switched off for minors. They could also have recommender systems that explain the main factors shaping a feed and give young users more control over personalization. The European Commission has published age-appropriate interaction guidelines that limit unsolicited contact and prevent minors from being added to groups without consent. Rules could also prohibit engagement-maximizing features that demand users’ attention, such as autoplay, infinite scroll, usage streaks, read receipts, and push notifications, by disabling or limiting them by default.
Governments should define measurable outcomes and fund independent evaluation, platforms should give researchers meaningful data access, and engineers should audit age-assurance systems for bias and data leakage. Schools, parents, and children themselves need a seat in designing the technology that’s designed to protect children.
If policymakers still decide to remove an infrastructure for youth connection, they should offer something better in return. Social media bans may reduce some forms of exposure to harmful content and may be justified for particular ages, services, or risks. But they are just one tool, not a comprehensive substitute for safer design, accountable platforms, digital literacy, institutional capacity, and non-commercial digital “third places”—moderated communities, creative spaces, and public-interest platforms designed for youth participation rather than profit.
The first wave of social media restrictions isn’t enough to keep children safe. Governments are still measuring what’s easiest to count, while neglecting harder-to-measure outcomes such as children’s access to safe third places and meaningful social connection, both online and offline. Until governments can show evidence that harm has actually declined, they will keep mistaking account removal for safety.
From Your Site Articles
Related Articles Around the Web
>
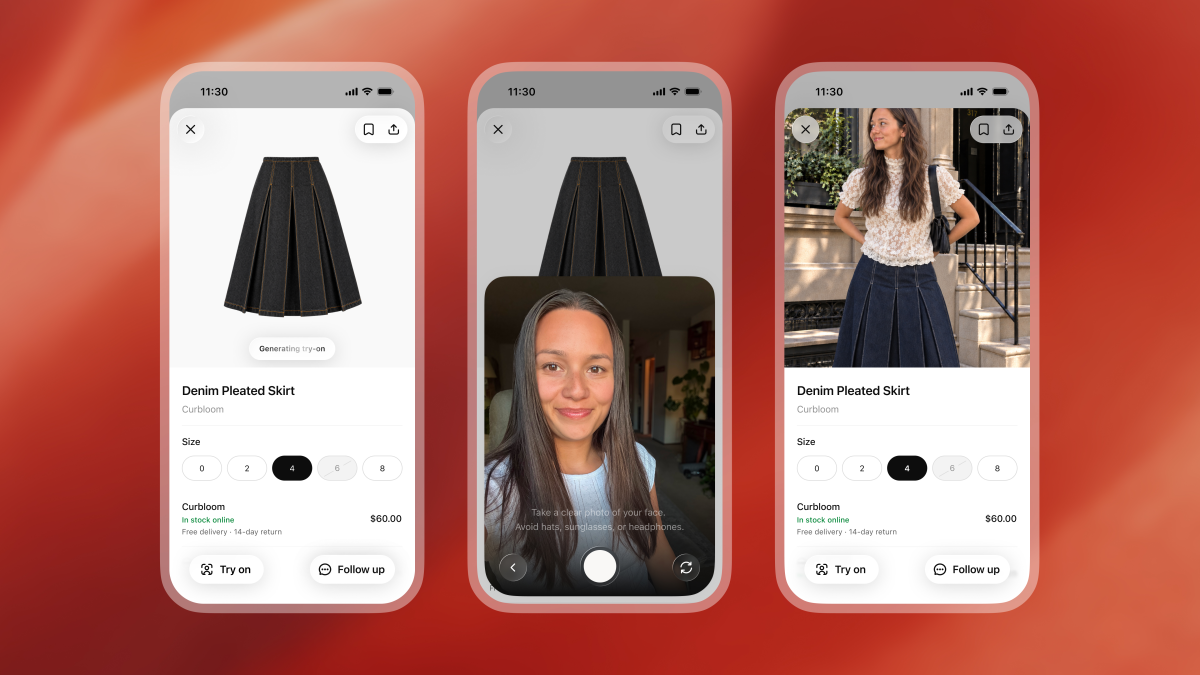
OpenAI is again experimenting with how its conversational AI assistant, ChatGPT, can help users as they shop online. On Thursday, the company announced the global launch of two new shopping features, including a way to virtually try on clothing and accessories and a new favoriting function that can help users save products they like for later reference.
The updates arrive at a time when AI assistants are exploring consumer use cases around shopping. OpenAI already had to pivot from one of its earlier ideas in this space, an instant checkout feature that ended up not performing well. More recently, agentic AI startup Instinct began pushing product recommendations to users, but some felt that the proactive recommendations were an overreach, more akin to ads than helpful suggestions.
OpenAI said its new shopping features leverage the newly launched ChatGPT Images 2.5 model, which the company claims produces more natural lighting and richer textures, follows editing instructions more reliably, and reduces image generation latency.
To start, virtual try-on allows ChatGPT users to upload a selfie or a full-body photo in order to visualize how an article of clothing or an accessory might look on them. This option will appear as a new “try on” button in ChatGPT’s shopping results. You can also upload an image of an item, like a web screenshot, and ask ChatGPT to try it on for you.
The other new option, Favorites, lets you save products you discover to a Library in the app so you can come back to them later. (These items will be saved alongside your try-on images, the company notes.)

OpenAI said that ChatGPT can help users shop in other ways, too.
For instance, you could describe a style that you’d like to try, then ask it to shop for the pieces needed to complete the look. Or, you could upload photos of celebrities’ outfits and ask it to find the items they’re wearing that are available for purchase.
The latter sees the assistant moving into areas that Pinterest and Google have dominated in recent years as sources for fashion inspiration and discovery that can convert to sales for online retailers.
Whether ChatGPT will become people’s first choice for this type of activity, however, remains to be seen — especially given that Google launched virtual try-on last year.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
Tech
Google thinks SpaceX’s Starship has to launch 1,600 times before space data centers get off the ground
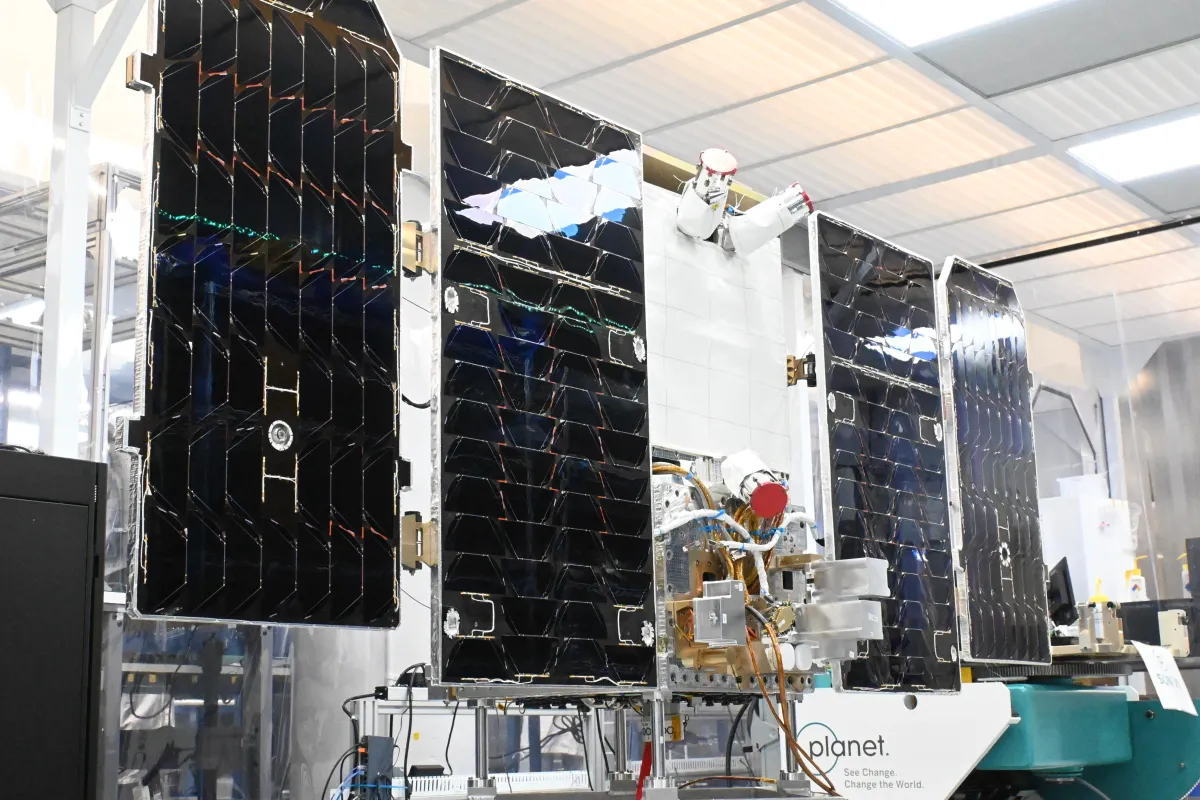
Google’s prototype of its orbital compute satellite took off today onboard a SpaceX rocket launched from California — the first time the tech giant has sent one of its advanced chips into space.
Built by Planet Labs, the satellite will prove that a Google Tensor Processing Unit, its competitor to Nvidia’s GPUs, can function in space. That means supplying a kilowatt of continuous power, cooling the chip, and running a series of models through their paces to see if anything goes wrong.
“We’ve done testing on the ground, but you know, there’s no test that’s completely as good as the real thing,” said Travis Beals, the Google executive managing Project Suncatcher, the tech giant’s plan to develop large-scale compute clusters in orbit around the Earth.
Once commissioned, the satellite will fire up its TPU in 15-minute bursts to avoid straining the satellite’s power and thermal management systems. This satellite is based on a standard platform built by Planet Labs, but the two companies are working on a demo expected to take flight next year that will see two satellites more purpose-built for advanced compute. Those future versions will attempt to collaborate via a laser communications link.
Suncatcher isn’t the only space AI payload on this SpaceX rocket, which is launching more than one hundred different payloads, including missions from Satlyt and Cowboy Space Company.
What sets the Google initiative apart from those startups (and indeed from SpaceX itself) is that it’s a long-term project.
The focus of this “long-term moonshot,” as Beals puts it, is on building for the space infrastructure and AI workloads that will exist in the future. The company envisions a network of 81 satellites flying in close formation, processing in parallel.
“The bandwidth and the latency between TPUs really, really matters when you’re trying to run a multi-rack workload…we’re trying to look ahead to not just what workloads exist today, but where they will be in five years,” Beals said. That’s largely because the rockets required to scale up orbital data centers in a cost-effective way don’t yet exist.
On Thursday, Google also released a peer-reviewed version of its white paper on orbital data centers, one of the most rigorous analyses available of how compute gets to orbit. The paper will be published in Joule.
One of the paper’s most notable aspects is how Google thinks about access to space. Although the researchers stress their analysis isn’t an economic feasibility study, it offers an interesting picture of how the company sees rockets becoming cheaper over time.
Like all data center companies, Google is looking to SpaceX to get its spacecraft off the ground. (Google is also a major investor in SpaceX.)
Arguing that Elon Musk’s rocket builders have achieved a price-reducing “learning curve” of about 20% a year since they launched the Falcon 1 rocket, the authors believe it’s reasonable to expect the company to deliver launch prices close to $200 per kilogram by 2035.
What will it take to do that? Based on the amount of payload launched by the Falcon 9, they think a similar cost-reduction trajectory will require Starship to fly 370,000 tons of payload into orbit. That’s something that would take it about 1,800 launches over the next ten years, or 180 a year—and that’s if it can fly 200 metric tons on each mission.
That’s a big ask for a vehicle that has never flown more than five times in a year. SpaceX predicts the company will be flying far more than that—Elon Musk has suggested Starship could achieve an hourly flight rate in 2029, for example, but Musk says a lot of things.
The good news, at least, in Google’s updated research is that it seems likely that its chips will survive the radiation of space. The company had to redo tests blasting the chips in a particle accelerator after they realized the configuration of the chips provided more shielding than they would actually experience. This produced slightly more errors in the chip’s logic circuitry, but the company is still confident its chips can handle large inference workloads in orbit for the five-year lifespan of a satellite.
“The error rate is very low if you’re thinking about typical inference operations, right? Like one in a million,” Beals said. “On the other hand, it was already problematic for doing, say, some mega-scale training run where you’re going to have many thousands of chips running for months.”
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
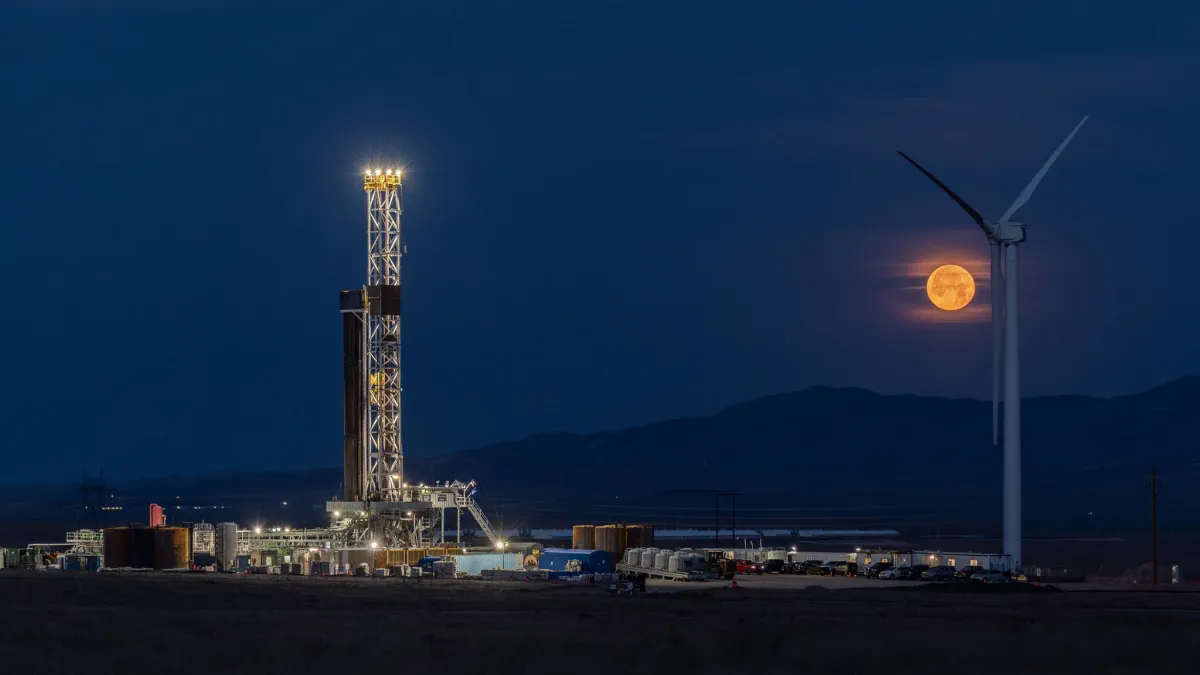
Geothermal company Fervo Energy announced Thursday morning that it had started selling electricity from its Cape Station power plant to the grid on September 30, one day ahead of schedule.
With it, Fervo becomes the first enhanced geothermal company to reach a key commercial milestone. The power plant synchronized with the grid about a week ago, bringing online the first third of what will soon become a 100-megawatt power plant.
The entire site could be much larger, though, with the potential to generate as much as 4 gigawatts of electricity, Fervo previously told TechCrunch.
“No team has ever built a project like this anywhere in the world, and we did it ahead of schedule,” Fervo co-founder and CEO Tim Latimer said in a statement.
From groundbreaking to commercial operations, the first block at Cape Station took 23 months to complete. As Fervo refines its process, it is aiming to complete future blocks in as little as 18 months.
That sort of speed to power should appeal to power-starved data center operators, who have been scouring every part of the energy sector for generating capacity. Geothermal can also be developed in phases, similar to how data centers are developed, allowing hyperscalers to bring racks online as demand ramps up.
Google, Southern California Edison, and others have committed to buying power from Fervo’s Cape Station project.
Fervo is one of several companies developing enhanced geothermal power plants. While traditional geothermal power taps heat sources close to the surface, Fervo and its peers are drilling deeper because deeper rock is hotter, opening more opportunities for development.
Fervo went public in May in an upsized IPO that raised $1.9 billion. It was founded in 2017, bringing drilling techniques and technologies from the oil and gas sector to the development of new geothermal resources. As a startup, the company raised more than $1.3 billion from investors including Breakthrough Energy Ventures, Congruent Ventures, and Capricorn Investment Group.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>

Anonymous Content To Produce Film Adaptation of Baldwin: A Love Story
Josh Hart says he is forgoing career-ending finger surgery, will play through pain

ChatGPT can now virtually try on clothes for you
-

 movies4 months ago
Search For Canadian TV Actor Stewart McLean Now Homicide Investigation
-

 Fashion9 years ago
These ’90s fashion trends are making a comeback in 2017
-
Fashion9 years ago
According to Dior Couture, this taboo fashion accessory is back
-
Fashion9 years ago
Model Jocelyn Chew’s Instagram is the best vacation you’ve ever had
-
Fashion9 years ago
Emily Ratajkowski channels back-to-school style
-
Fashion9 years ago
9 Celebrities who have spoken out about being photoshopped
-
 Anime4 months ago
Rurouni Kenshin: Hokkaido Arc Manga Takes 1-Issue Break – News
-

 Anime3 months ago
HIDIVE to Stream English Dubs for The World Is Dancing, The Forsaken Saintess and Her Foodie Roadtrip in Another World, The Dangers in My Heart: The Movie Anime – News