
Tech
The Future of Physical AI Isn’t Smarter Robots, It’s Smarter Interfaces


This sponsored article is brought to you by Wetour Robotics.
A field technician on a wind turbine, harness clipped, both hands on a wrench, needs to send a command to the diagnostic device hanging at her belt. A logistics worker on a loading dock, gloves on, eyes on the pallet, needs to redirect a connected lift. A person using an assistive mobility device on a crowded street wants to nudge it forward without taking out a phone or speaking aloud. None of these moments call for a smarter robot. They call for a smarter way to be heard by the machines that already exist.
The industry has been building from one side
The past three years of Physical AI have been a story of remarkable progress on the robot side of the loop. Companies like Boston Dynamics, Figure, and Unitree have advanced actuators, locomotion, and dexterity to a level that would have seemed implausible a decade ago. Google DeepMind’s Gemini Robotics has redefined what vision-language-action models can do in unstructured settings. The trajectory of the hardware and the foundation models is real, and it is accelerating.
But there is another side to this loop, and it has been treated as a solved problem for too long. The interface between humans and machines has defaulted, for 40 years, to three input modalities: screens, buttons, and voice. Each of those assumes the user can stop, look down, and translate intent into structured commands. That assumption breaks the moment the work moves into a real environment. On a turbine. On a dock. On a sidewalk. In any setting where hands are occupied, eyes are committed, or speaking is impractical, the conventional interface stack quietly fails.
Spatial Intent Fusion is the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent: Your body is the interface.
The bottleneck on the human side of the loop is becoming as important as the one on the machine side. And solving it requires a different question. Not how do we make the robot more capable, but how do we let the human participate in the computing system as naturally as the robot already does.
Wetour Robotics’ bet: put the human back into the computing loop
Wetour Robotics is betting that the next architectural leap in Physical AI is not about making the robot more capable. It is about making the human a first-class node in the computing network, with the same kind of low-latency, high-fidelity participation that connected devices already enjoy.
Wetour Robotics’ engineers frame the problem this way: a wristband that recognizes a gesture is not enough. A camera that recognizes a scene is not enough. The information a human carries about what they are about to do is distributed across multiple channels, including where their body is in space, what their eyes are attending to, and what their muscles are preparing to do, and any single channel observed in isolation is ambiguous. Reconstructing intent reliably means fusing those channels at the operating system level, with latency low enough that the loop feels closed rather than mediated.
This approach has a name. Wetour Robotics calls it Spatial Intent Fusion: the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent, fused into a single real-time command for any connected physical device. It is the technical implementation behind a simpler positioning statement the company uses externally: your body is the interface.
 Orchestra is a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Wetour Robotics
The architecture: three layers, four engines, one loop
Orchestra is not a single device but a layered platform, designed from the start to be sensor-flexible and actuator-agnostic. The architecture decomposes into three perception layers and four coordination engines.
Orchestra itself is the local compute and orchestration core: a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Edge inference is non-negotiable for this application. Full-chain latency from biosignal acquisition to actuator command is held under 100 milliseconds, the envelope inside which closed-loop control feels natural rather than laggy.
VisionLink handles visual and spatial perception. Cameras feed into vision models that identify objects, estimate distances, and track environmental context. VisionLink is designed not as a passive recognition layer but as a real-time command generator: its outputs feed directly into Orchestra OS to be fused with biosignal data.
Conductor is the biosignal pipeline. It ingests raw surface electromyographic (sEMG) data from a wrist-worn device, classifies temporal patterns into discrete gestures or continuous control signals, and outputs actuator commands. The technically interesting property of sEMG for this use case is that the signal precedes visible motion. Motor unit action potentials appear at the skin surface roughly 50 to 80 milliseconds before a finger completes the corresponding gesture. Wetour Robotics calls this property pre-motion intent sensing, and it is what allows Orchestra to anticipate user intent rather than react to it.
On top of the three perception layers, Orchestra OS runs four coordination engines. The Perception Engine ingests and normalizes raw sensor streams. The Intent Engine performs Spatial Intent Fusion across modalities, resolving what the user is trying to do given where they are, what they are looking at, and what their hand is signaling. The Orchestration Engine translates intent into device-specific command sequences for any connected actuator. The Safety Engine arbitrates conflicting commands, enforces operational envelopes, and gates execution against runtime safety conditions.
Wetour Robotics
The trade-offs we’re honest about
No system that bridges the human body and the digital world is finished. Three engineering challenges remain open, and the company addresses each with a deliberate trade-off rather than a claim of having fully solved it.
Baseline stability of sEMG under motion. In a stationary user, continuous gesture recognition from sEMG is reliable. Once the user is walking, climbing, or otherwise moving, motion artifacts and electrode drift degrade the signal in ways that are difficult to fully compensate for. Rather than overpromise on continuous control in dynamic settings, Orchestra defaults to a smaller set of robust discrete gestures in complex operating environments, and reserves continuous control modes for contexts where the signal-to-noise ratio supports them.
Miniaturization of edge AI compute. Running the Orchestra control loop entirely at the edge requires real on-device inference, which has historically meant trading off between compute capacity, battery life, and form factor. Wetour Robotics’ approach has been a compact carrier board paired with a thermal design and a battery module sized for all-day wearability. The result is a hub that travels with the user rather than tethering them to a desk, and that performs the full perception-to-actuation loop without offloading to the cloud.
Heterogeneity of third-party device protocols. The actuator side of the loop is a fragmented landscape. Different manufacturers expose different command interfaces, different communication stacks, and different safety conventions, and a Physical AI operating system has to integrate with all of them. Wetour Robotics uses an AI-agent layer to negotiate connection and protocol translation adaptively, so that Orchestra OS can ingest data from a wide range of devices, run them through neural network models that infer human intent, and emit the right command on the right protocol for the device on the other end.
Why this matters, and why it helps the rest of the field
The history of computing is a history of interface revolutions. Command lines gave way to graphical user interfaces, which gave way to touch, which gave way to voice. Each transition expanded who could participate in the system and what they could do with it. The next transition is not about a new screen or a new microphone. It is about treating the human body itself as a participant in the computing network, capable of contributing intent at the same speed and fidelity that any other connected node can.
The history of computing is a history of interface revolutions. The next transition is not about a new screen or a new microphone — it is about treating the human body itself as a participant in the computing network.
This path is not a competitor to the work being done on humanoid robots, foundation models for embodied AI, and dexterous manipulation. It is the missing complement to that work. The hardest open problem for humanoid systems is the data: every natural interaction between a human and the physical world is a potential training signal, and most of those interactions are currently invisible to any computing system. As more humans become first-class nodes in the loop, those interactions become observable, structured, and ultimately useful for training the next generation of embodied AI, including the humanoid robots being developed today.
In other words: putting the human back into the computing loop is not just about better interfaces for individual users. It is about generating the kind of grounded, in-the-wild human-machine interaction data that the broader Physical AI ecosystem will need to keep advancing. The robot side and the human side of the loop are not two competing futures. They are two halves of the same one.
That is what Wetour Robotics means when it says: Your body is the interface.
Learn more at wetourrobotics.com.
>
OpenAI will start adding an invisible watermark to text generated by ChatGPT and Codex in the European Union to comply with the EU AI Act, the company said Monday in a blog post.
The EU AI Act’s transparency rules, which took effect on August 2, require AI companies to mark AI-generated content in a way other systems can identify.
OpenAI said the watermark will roll out over the coming weeks to eligible ChatGPT and Codex users on all plans, but only in the EU. Developers using OpenAI’s API anywhere in the world can turn it on for select models starting today; it’s off by default. OpenAI said it is not making text watermarking a global default at launch.
The watermark is not an actual symbol, but works by subtly shaping the model’s word choices, leaving a pattern readers can’t see, but a detector can pick up. Because it lives in the words themselves, it travels with the text when it’s copied and pasted. OpenAI said the watermark doesn’t identify the user, and that it saw no meaningful change in its models’ performance with it switched on.
OpenAI also published a technical report for its method, called textGrain, alongside the announcement. Co-written with researchers from the University of Pennsylvania and Yale, it walks through an example of using a secret key to sort next-word predictions to finish the sentence. Add hundreds of these nudges together, and the detector can spot AI-generated content using only the text and the key.
Can the watermark be removed by editing? OpenAI’s tests suggest yes. In one test, replacing 10% of words with synonyms dropped detection from about 92% to 66%. The company also said short passages, math answers, and translated text are harder to detect.

“These limitations contribute to our decision to provide initial detector access only to approved researchers and expert organizations, who can help us evaluate reliability and responsible uses,” said the company.
OpenAI also cautioned that a missing watermark “does not prove human authorship.” The text could be too short or too heavily edited, or it could come from another company’s AI.
“[Watermarks] can indicate that an OpenAI system generated or processed part of a passage, but not how much human judgment, editing, or creativity went into it,” the company said.
The announcement comes two months after Anthropic said it would watermark text generated by Claude, a move it’s applying worldwide. That decision drew backlash from some Claude users, who argued they had supplied “the instructions, context, decisions” while Claude was just “the tool.”
OpenAI had built a text watermark before but held off on releasing it, partly over concerns that users would switch to rivals that didn’t watermark, The Wall Street Journal reported in 2024.
Anthropic, Google, Meta, Microsoft and OpenAI are among the companies that have committed to following the EU’s code of practice on AI-generated content.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
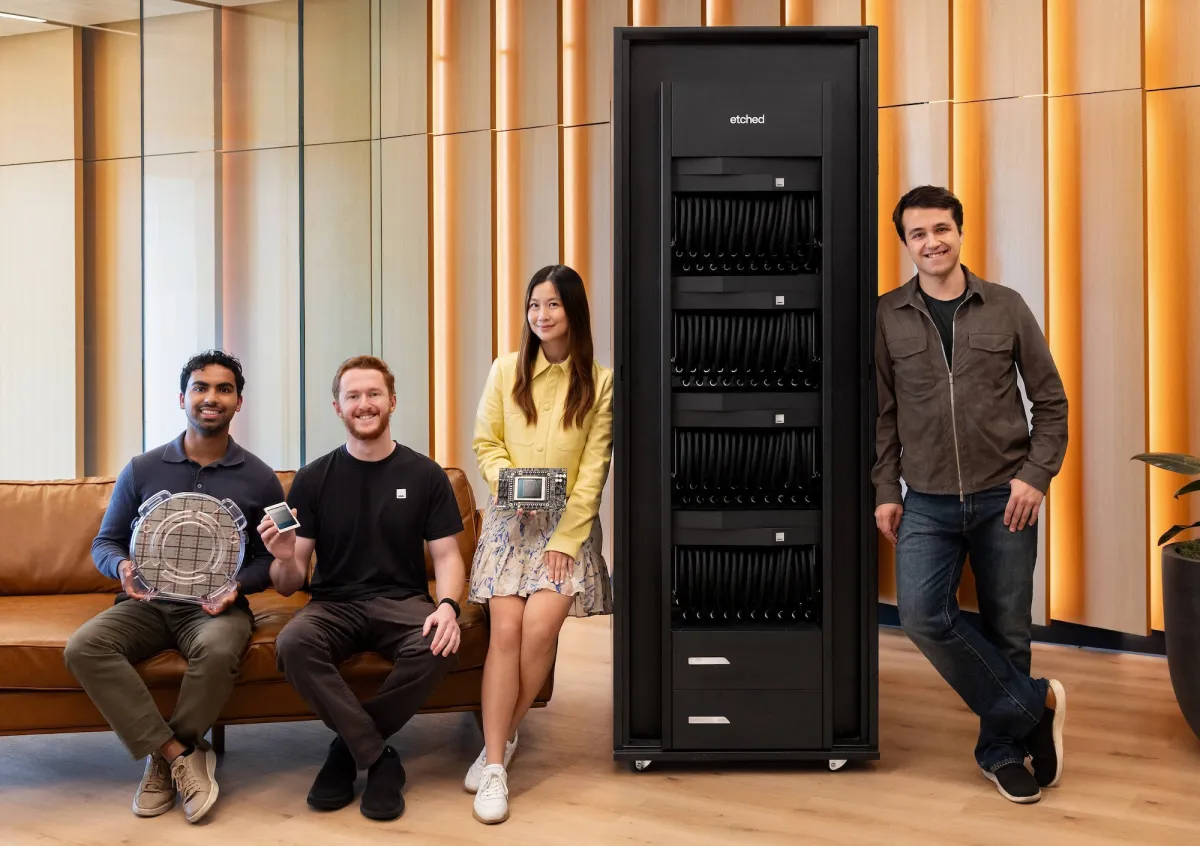
Although it’s only been a couple of months since Etched raised $700 million at a $21 billion valuation, the AI chip startup is already being plied with investment offers at double or more its value, according to people familiar with the company.
Etched is reviewing incoming bids that range from $40 billion from top-tier investors to $50 billion from lesser-known backers, one person said. These fundraising talks are early, so terms of any deal, should one happen, may change. Etched declined to comment.
While this may seem like a fast time-table to raise another mega round, Etched is pursuing a particularly expensive segment of the AI industry: building full AI hardware systems powered by its own proprietary chips. The person familiar with these offers said that if it raises as much as its last round, this could give Etched a cushion of as much as 3.5 years of runway.
There are reasons why VCs are hot to own a piece of Etched. The four-year-old startup shows promise of challenging Nvidia. Not only did quant trading firm Jane Street lead the last $700 million round, it is also a customer that took delivery of an early system. Etched said in July that it had already secured $1 billion in customer orders, including the one from Jane Street, after manufacturing its test chip at a TSMC factory this summer.
Co-founder and COO Robert Wachen previously told TechCrunch that investors are so enthusiastic because Etched has designed two new components from scratch to speed up inference — the computing process that happens after a user submits a prompt.
The company claims its chips can process more tokens faster and at a lower cost than Nvidia’s. That’s the reason its processors have been so attractive to Jane Street for whom a microscopic advantage in speed can yield massive profits.
The startup has also impressed investors with its ability to attract engineers from Nvidia, with roughly 15% of Etched’s 400-person workforce having previously worked at the chip giant, according to the Wall Street Journal.
Etched also operates a new 10-megawatt datacenter in Silicon Valley and established a facility in Taiwan to coordinate production near TSMC.
Co-founders Gavin Uberti and Chris Zhu famously met in an advanced math course at Harvard, while Wachen was Uberti’s roommate and they dropped out to pursue the company.
In terms of fast rounds at big leaps in valuations, Etched already has a history of them. The startup announced a $300 million round at a $10.3 billion led by Sequoia in July. It announced the $700 million round at a $21 billion valuation in September. Back-to-back funding rounds, which essentially act as a single financing split into two tranches with separate valuations, are increasingly common among the buzziest startups.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>

Reflection AI is officially unveiling Beam, its first frontier, open-weight AI model. The two-year-old, Brooklyn-based startup claims Beam matches the performance of leading Chinese open models on advanced reasoning benchmarks at dramatically lower costs, a claim that could heat up the race to build a Western answer to DeepSeek, Qwen, and Z.ai.
Reflection’s announcement confirms reporting from Axios over the weekend that the startup was close to a launch. The company shared new details in a lengthy blog post Monday, which described Beam as a text-only mixture-of-experts model trained on high-compute reinforcement learning to be effective at reasoning, coding, and agentic tasks at “a fraction of the token cost and inference time compute” of rivals.
Beam is a 501-billion-parameter model with 23 billion active parameters. It was pre-trained on 23.8 trillion tokens and has a 1 million token context window. To compare, Z.ai’s GLM-5.2 has roughly 744 billion total parameters with 40 billion active.
Reflection’s performance claims haven’t been independently verified, but on advanced reasoning benchmarks, the company says Beam scores on par with Z.ai’s GLM-5.2 and outperforms today’s leading Western open models while using “3-4x less inference compute.” Reflection calls it a “workhorse model” for enterprises, the public sector, and developers.
Reflection is positioning itself against closed labs like Anthropic and OpenAI, against popular open models from Chinese developers, and against Western players like Mistral, Meta, and Cohere. Its most direct U.S. rival might be Inkling, the open model from Mira Murati’s Thinking Machines Lab released in July. Reflection’s own benchmarks show that Beam outscores Inkling on four coding tests where both report results, but Inkling is a multimodal model and Beam is text-only.
Reflection was founded in 2024 by two former Google DeepMind researchers and has raised roughly $4.7 billion from backers including Nvidia, Sequoia Capital, and Lightspeed Venture Partners, per PitchBook. Its last round valued the company at a $25 billion pre-money valuation.
The startup has also been locking up compute — a key ingredient needed to train frontier models capable of luring customers away from Anthropic’s and OpenAI’s closed models, as well as the cheaper open-weight models from Chinese labs. This summer, Reflection signed deals collectively worth more than $7 billion with SpaceX and Nebius to secure access to Nvidia’s GB300 chips through 2029.
Reflection is aiming Beam and future models at enterprises and sovereign nations. The pitch is to build “AI factories,” a product that would let institutions build their own customized, local AI system by training Reflection’s AI models on their own proprietary data. Nvidia CEO Jensen Huang, whose company backs Reflection, has long championed the “AI factory” idea and pushed to strengthen the open AI ecosystem — a vision that would also benefit Nvidia, whose GPUs would power those systems.
Axios reported that hedge funds and trading firms are among those eager to build such systems. Reflection has already begun testing the concept of a sovereign AI factory partnership with Shinsegae Group in South Korea.
Reflection says it will release Beam’s weights and full technical details this month, with distribution through hyperscalers and neoclouds and integrations across open source libraries at launch.
Reflection did not respond in time to TechCrunch’s requests for more information.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>

China Open: Coco Gauff condemns racist abuse on social media after incident during Sun Xinran match

Why Tom Cruise’s Digger Bombed at the Box Office
USWNT calls up Jaelin Howell to replace injured Sam Coffey for Spain friendlies
-

 movies5 months ago
Search For Canadian TV Actor Stewart McLean Now Homicide Investigation
-

 Fashion9 years ago
These ’90s fashion trends are making a comeback in 2017
-
Fashion9 years ago
According to Dior Couture, this taboo fashion accessory is back
-
Fashion9 years ago
Model Jocelyn Chew’s Instagram is the best vacation you’ve ever had
-
Fashion9 years ago
Emily Ratajkowski channels back-to-school style
-
Fashion9 years ago
9 Celebrities who have spoken out about being photoshopped
-
 Anime4 months ago
Rurouni Kenshin: Hokkaido Arc Manga Takes 1-Issue Break – News
-

 Anime3 months ago
HIDIVE to Stream English Dubs for The World Is Dancing, The Forsaken Saintess and Her Foodie Roadtrip in Another World, The Dangers in My Heart: The Movie Anime – News