
Tech
The Future of Physical AI Isn’t Smarter Robots, It’s Smarter Interfaces


This sponsored article is brought to you by Wetour Robotics.
A field technician on a wind turbine, harness clipped, both hands on a wrench, needs to send a command to the diagnostic device hanging at her belt. A logistics worker on a loading dock, gloves on, eyes on the pallet, needs to redirect a connected lift. A person using an assistive mobility device on a crowded street wants to nudge it forward without taking out a phone or speaking aloud. None of these moments call for a smarter robot. They call for a smarter way to be heard by the machines that already exist.
The industry has been building from one side
The past three years of Physical AI have been a story of remarkable progress on the robot side of the loop. Companies like Boston Dynamics, Figure, and Unitree have advanced actuators, locomotion, and dexterity to a level that would have seemed implausible a decade ago. Google DeepMind’s Gemini Robotics has redefined what vision-language-action models can do in unstructured settings. The trajectory of the hardware and the foundation models is real, and it is accelerating.
But there is another side to this loop, and it has been treated as a solved problem for too long. The interface between humans and machines has defaulted, for 40 years, to three input modalities: screens, buttons, and voice. Each of those assumes the user can stop, look down, and translate intent into structured commands. That assumption breaks the moment the work moves into a real environment. On a turbine. On a dock. On a sidewalk. In any setting where hands are occupied, eyes are committed, or speaking is impractical, the conventional interface stack quietly fails.
Spatial Intent Fusion is the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent: Your body is the interface.
The bottleneck on the human side of the loop is becoming as important as the one on the machine side. And solving it requires a different question. Not how do we make the robot more capable, but how do we let the human participate in the computing system as naturally as the robot already does.
Wetour Robotics’ bet: put the human back into the computing loop
Wetour Robotics is betting that the next architectural leap in Physical AI is not about making the robot more capable. It is about making the human a first-class node in the computing network, with the same kind of low-latency, high-fidelity participation that connected devices already enjoy.
Wetour Robotics’ engineers frame the problem this way: a wristband that recognizes a gesture is not enough. A camera that recognizes a scene is not enough. The information a human carries about what they are about to do is distributed across multiple channels, including where their body is in space, what their eyes are attending to, and what their muscles are preparing to do, and any single channel observed in isolation is ambiguous. Reconstructing intent reliably means fusing those channels at the operating system level, with latency low enough that the loop feels closed rather than mediated.
This approach has a name. Wetour Robotics calls it Spatial Intent Fusion: the simultaneous processing of three streams of human-centered information, namely spatial position, visual context, and gestural intent, fused into a single real-time command for any connected physical device. It is the technical implementation behind a simpler positioning statement the company uses externally: your body is the interface.
 Orchestra is a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Wetour Robotics
The architecture: three layers, four engines, one loop
Orchestra is not a single device but a layered platform, designed from the start to be sensor-flexible and actuator-agnostic. The architecture decomposes into three perception layers and four coordination engines.
Orchestra itself is the local compute and orchestration core: a portable intelligent hub running the operating system that handles sensor fusion, intent inference, command translation, and safety arbitration. The reference compute platform is NVIDIA Jetson Orin Nano Super, which provides enough on-device inference capacity to keep the entire control loop at the edge, with no cloud dependency on the critical path. Edge inference is non-negotiable for this application. Full-chain latency from biosignal acquisition to actuator command is held under 100 milliseconds, the envelope inside which closed-loop control feels natural rather than laggy.
VisionLink handles visual and spatial perception. Cameras feed into vision models that identify objects, estimate distances, and track environmental context. VisionLink is designed not as a passive recognition layer but as a real-time command generator: its outputs feed directly into Orchestra OS to be fused with biosignal data.
Conductor is the biosignal pipeline. It ingests raw surface electromyographic (sEMG) data from a wrist-worn device, classifies temporal patterns into discrete gestures or continuous control signals, and outputs actuator commands. The technically interesting property of sEMG for this use case is that the signal precedes visible motion. Motor unit action potentials appear at the skin surface roughly 50 to 80 milliseconds before a finger completes the corresponding gesture. Wetour Robotics calls this property pre-motion intent sensing, and it is what allows Orchestra to anticipate user intent rather than react to it.
On top of the three perception layers, Orchestra OS runs four coordination engines. The Perception Engine ingests and normalizes raw sensor streams. The Intent Engine performs Spatial Intent Fusion across modalities, resolving what the user is trying to do given where they are, what they are looking at, and what their hand is signaling. The Orchestration Engine translates intent into device-specific command sequences for any connected actuator. The Safety Engine arbitrates conflicting commands, enforces operational envelopes, and gates execution against runtime safety conditions.
Wetour Robotics
The trade-offs we’re honest about
No system that bridges the human body and the digital world is finished. Three engineering challenges remain open, and the company addresses each with a deliberate trade-off rather than a claim of having fully solved it.
Baseline stability of sEMG under motion. In a stationary user, continuous gesture recognition from sEMG is reliable. Once the user is walking, climbing, or otherwise moving, motion artifacts and electrode drift degrade the signal in ways that are difficult to fully compensate for. Rather than overpromise on continuous control in dynamic settings, Orchestra defaults to a smaller set of robust discrete gestures in complex operating environments, and reserves continuous control modes for contexts where the signal-to-noise ratio supports them.
Miniaturization of edge AI compute. Running the Orchestra control loop entirely at the edge requires real on-device inference, which has historically meant trading off between compute capacity, battery life, and form factor. Wetour Robotics’ approach has been a compact carrier board paired with a thermal design and a battery module sized for all-day wearability. The result is a hub that travels with the user rather than tethering them to a desk, and that performs the full perception-to-actuation loop without offloading to the cloud.
Heterogeneity of third-party device protocols. The actuator side of the loop is a fragmented landscape. Different manufacturers expose different command interfaces, different communication stacks, and different safety conventions, and a Physical AI operating system has to integrate with all of them. Wetour Robotics uses an AI-agent layer to negotiate connection and protocol translation adaptively, so that Orchestra OS can ingest data from a wide range of devices, run them through neural network models that infer human intent, and emit the right command on the right protocol for the device on the other end.
Why this matters, and why it helps the rest of the field
The history of computing is a history of interface revolutions. Command lines gave way to graphical user interfaces, which gave way to touch, which gave way to voice. Each transition expanded who could participate in the system and what they could do with it. The next transition is not about a new screen or a new microphone. It is about treating the human body itself as a participant in the computing network, capable of contributing intent at the same speed and fidelity that any other connected node can.
The history of computing is a history of interface revolutions. The next transition is not about a new screen or a new microphone — it is about treating the human body itself as a participant in the computing network.
This path is not a competitor to the work being done on humanoid robots, foundation models for embodied AI, and dexterous manipulation. It is the missing complement to that work. The hardest open problem for humanoid systems is the data: every natural interaction between a human and the physical world is a potential training signal, and most of those interactions are currently invisible to any computing system. As more humans become first-class nodes in the loop, those interactions become observable, structured, and ultimately useful for training the next generation of embodied AI, including the humanoid robots being developed today.
In other words: putting the human back into the computing loop is not just about better interfaces for individual users. It is about generating the kind of grounded, in-the-wild human-machine interaction data that the broader Physical AI ecosystem will need to keep advancing. The robot side and the human side of the loop are not two competing futures. They are two halves of the same one.
That is what Wetour Robotics means when it says: Your body is the interface.
Learn more at wetourrobotics.com.
>
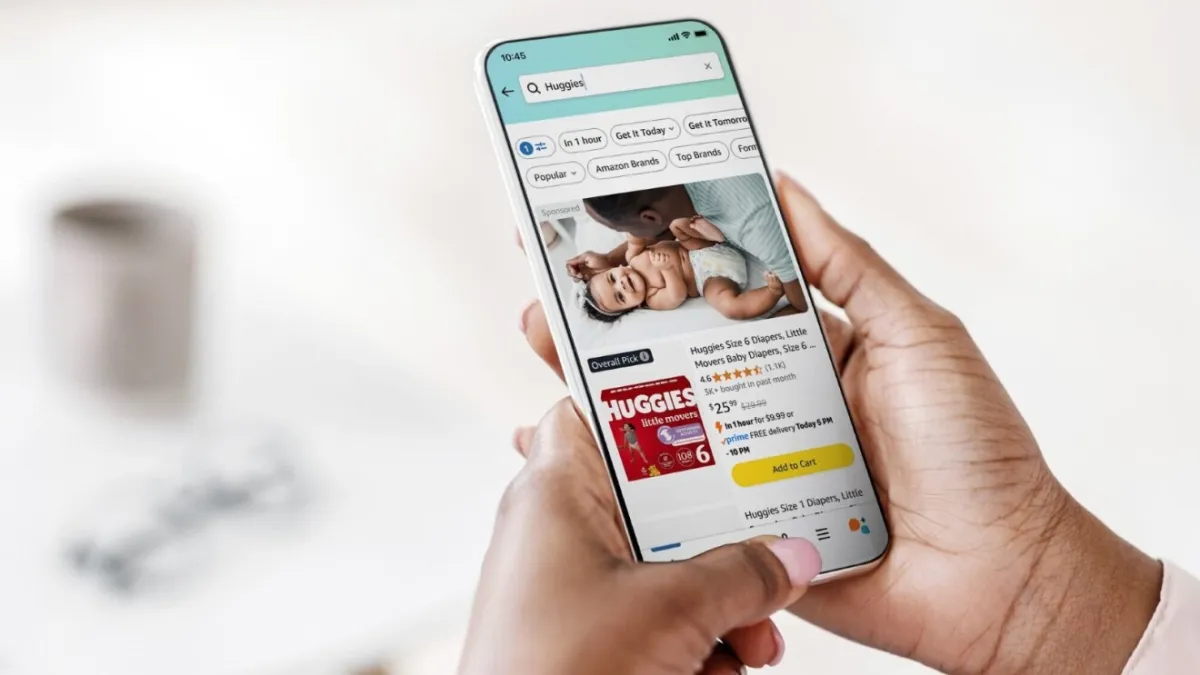
It shouldn’t come as a surprise that Amazon collects data about you based on what you buy. If you buy a lot of cat litter, Amazon will probably infer that you have cats, or if you buy a lot of anti-acne skin products, then Amazon might guess you’re prone to breakouts. Even if we know that Amazon customizes our shopping experiences based on our purchase history, it still comes as a surprise to see all of these personal details laid out in a convenient list. Especially when those details get uncomfortably intimate.
One Threads user came across this section of her Amazon settings, where you can see who the shopping giant thinks you are, and alongside more benign assumptions like “Shops from women’s departments” and “Probably owns a Shark robot vacuum,” she found that Amazon assumes she “has flat buttocks.”
“I stumbled upon a page of assumptions that Amazon has made about me based on my purchases and I’m literally speechless,” an Amazon customer, @fangirlinmegan, wrote on Threads. “I mean it ain’t wrong but damn did you have to call me out like that?”
In less than a day, the post garnered over a million views, including many from users who were curious what their own Amazon profiles might reveal. Here’s how you find out.
On desktop, you can find this page by hovering over where Amazon says “Hello, [your name]” in the upper right corner. Then click “Account” under the “Your Account” section. Under the “Ordering and shopping preferences” section, click “Your Shopping preferences.” From here, you can add in information of your own, like your shoe size, interests, and dietary preferences. But we’re not here to tell Amazon that it should stop selling you beef jerky since you’re a vegetarian. We’re here to see if Amazon thinks you have “flat buttocks.” When you scroll to the bottom of the page, you’ll see a blue hyperlinked option that says “Manage your information.” Once you click that, you’ll see what dirt Amazon has on you.
On the mobile app, you can get here by clicking the hamburger icon from the bottom menu bar, then navigating to “Account” > “Shopping preferences” > “About you.”
For me, Amazon has gleaned that I am someone who “practices photography,” “plays collectible card games,” and is “invested in the Apple ecosystem.” This is all true. Amazon has even flattered me by noting that I “read diverse non-fiction,” to which I say — why yes, I am indeed an open-minded intellectual with a thirst for knowledge. Thank you for noticing.
Other colleagues of mine found that Amazon correctly noted their interests in vinyl records and ceramics, as well as a penchant for “natural materials” in home decor and clothing that “prioritizes comfort.” None of us had anything as affronting as “has flat buttocks,” but the Threads user noted that this was likely because she had purchased “butt scrunch leggings.”
Tech companies know too much about us, and it’s jarring to realize just how closely they’re paying attention to how we use their platforms. We live in a world of alarming surveillance, but at least I know that Amazon doesn’t think my butt is flat.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
Apple is working on a new ecosystem of smart home devices via a partnership with LG, Bloomberg has reported.
The new devices — which include a smart lock, a thermostat, and a doorbell — are designed to integrate with the company’s smart home hub, another upcoming product that will reportedly launch on Oct. 13th. That hub is expected to include a 6-inch square display that can be placed on a countertop or mounted on a wall.
The two companies are also working on a slate of security cameras, including models for indoor, outdoor and a floodlight. The LG devices are expected to be announced, if not formally released, next week, too. TechCrunch reached out to Apple for more information.
Interestingly, the devices will reportedly carry the LG brand — despite being developed by both companies.
The new products could aptly be read as a swipe at Amazon’s smart home offerings, which currently offers a variety of similar products, including its Ring home security cameras.
Apple has sought to push into new territory with its recent hardware releases. One of those new territories is an expanded smart home presence.
>
Melius, an AI platform for generating ad campaigns, images, and videos, announced on Tuesday that it raised a total of $25 million in funding, including a $20 million Series A led by CRV and a $5 million seed round led by General Catalyst.
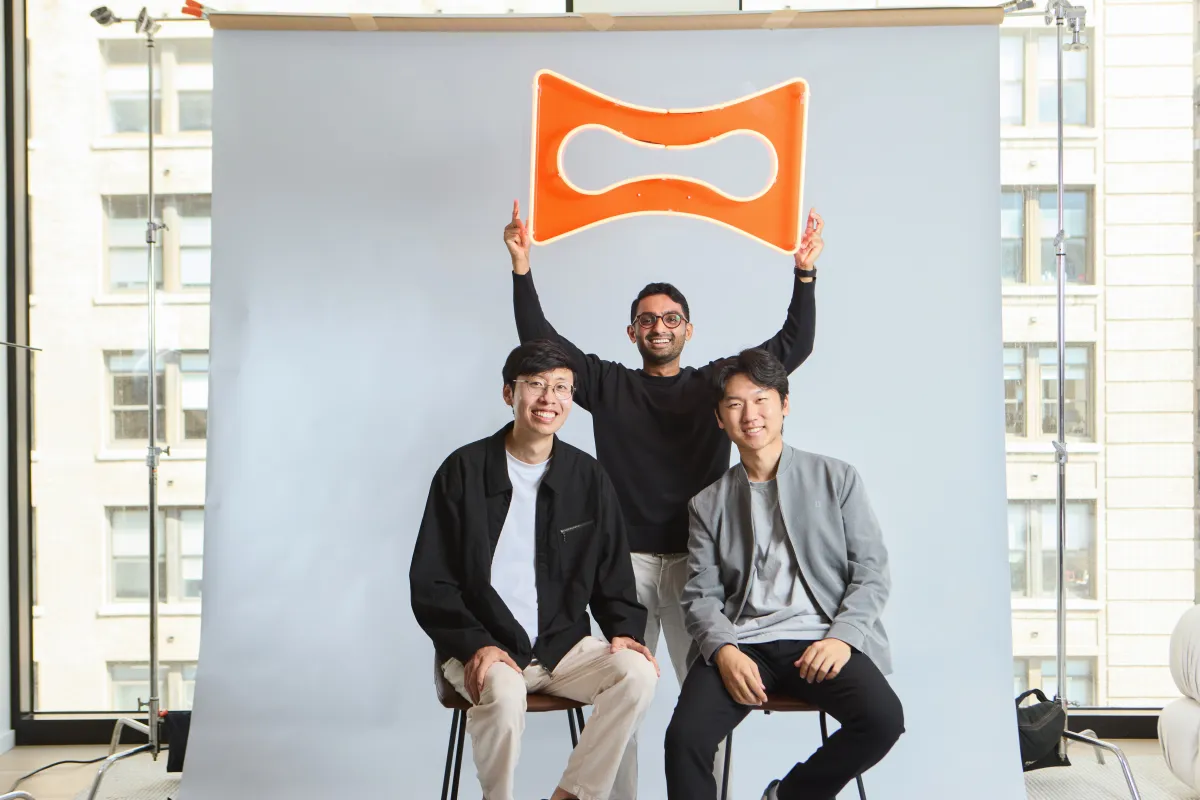
While the startup claims to have hit more than $1 million in annualized revenue within two months of coming out of stealth in July, co-founder Joowon Kim (pictured on right) admits that Melius didn’t hit it out of the park initially.
When the New York-based company first launched over a year ago, Kim and his co-founders, Young Kim (pictured on left) and Arnav Ramu (pictured center) set out to build an AI-powered performance marketing tool. The three knew each other from working as engineers at Ramp, the corporate spending and finance software company.
More than six months after building the product, the co-founders decided their original idea didn’t “have legs,” Joowon Kim told TechCrunch.
Instead of helping marketers manage and optimize ad spend, the team chose to focus on what it saw as a much larger opportunity: building the tools that generate the creative assets and campaigns themselves.
“We scrapped the entire codebase; we burned all of it,” Kim said. Melius quickly went to work on an entirely new product. Nearly a year after its initial launch, it revealed a platform that it describes as an “agents lab for creative work.”
Melius is far from the only startup helping ad agencies, marketers, and brands generate creative assets and campaigns with AI. Competitors include rapidly growing Higgsfield, which was valued at $5.4 billion in August, as well as other small startups, including Krea and Flora AI.
Kim isn’t concerned about the competition.
He acknowledged that Higgsfield, a three-year-old that has hit over $700 million in annualized revenue, “is growing like mad,” but according to Kim, the size of the market is so large that it can support multiple competitors.
“There are a lot of players, which is pretty exciting,” he told TechCrunch. “That means there are customers to be won and there is demand in this space.”
As for why former Ramp engineers are building an ad generation product, Kim, who describes himself as a social media influencer, says he has been passionate about making short videos since elementary school and once dreamed of becoming a famous YouTuber.
“I tried my best to make vlogs,” he said. “My dad was great at using FinalCut Pro, but I wasn’t.”
Those early vlogs never quite took off, but his fascination with making digital media remained.
Now, with Melius, he’s building the tool he always wanted: a platform where anyone, including seasoned creative directors, can turn their ideas into reality using plain language.
When you purchase through links in our articles, we may earn a small commission. This doesn’t affect our editorial independence.
>
Where does Mauricio Dubón's home run robbery rank? Let's check the Andruw Jones tape

Skydance Co-CEOs Insist Its Massive Debt Is Manageable

Premier League predicted and xG table 26/27 – latest Sky Sports supercomputer standings for title, top four, relegation | Football News
-

 movies5 months ago
Search For Canadian TV Actor Stewart McLean Now Homicide Investigation
-

 Fashion9 years ago
These ’90s fashion trends are making a comeback in 2017
-
Fashion9 years ago
According to Dior Couture, this taboo fashion accessory is back
-
Fashion9 years ago
Model Jocelyn Chew’s Instagram is the best vacation you’ve ever had
-
Fashion9 years ago
Emily Ratajkowski channels back-to-school style
-
Fashion9 years ago
9 Celebrities who have spoken out about being photoshopped
-
 Anime4 months ago
Rurouni Kenshin: Hokkaido Arc Manga Takes 1-Issue Break – News
-

 Anime3 months ago
HIDIVE to Stream English Dubs for The World Is Dancing, The Forsaken Saintess and Her Foodie Roadtrip in Another World, The Dangers in My Heart: The Movie Anime – News